Leanpub Header

Skip to main content

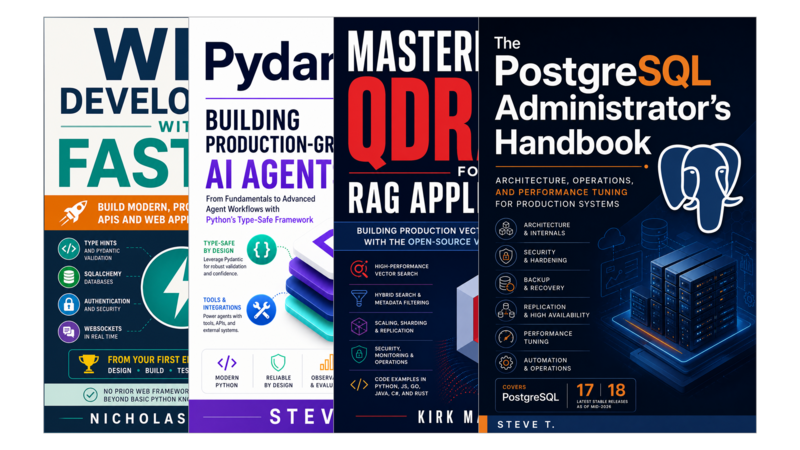
Mastering Qdrant for RAG Applications

Building Production Vector Search Systems with the Open-Source Vector Database

Mastering Qdrant for RAG Applications
This book is 100% completeLast updated on 2026-10-11

Mastering Qdrant for RAG Applications is your practical guide to building production-ready RAG systems with the leading open-source vector database. Learn how to design, optimize, and scale high-performance vector search using Qdrant through clear explanations, real-world examples, and hands-on code.

Minimum price

$19.00

$29.00

You pay

Author earns

$

Also available for 1 book credit with a Reader Membership

PDF
EPUB
WEB
APP
192
Pages
About

About

About the Book

Retrieval-Augmented Generation has become the dominant architecture for production AI applications, and vector databases form its critical retrieval layer. This book takes you from the fundamentals of embeddings and similarity search through to advanced distributed deployments of Qdrant, the high-performance open-source vector database written in Rust. You will learn every facet of Qdrant's feature set: collections, points, payloads, HNSW indexing, quantization, hybrid search with dense and sparse vectors, metadata filtering, faceting, sharding, replication, security, monitoring, and scaling. Through detailed code examples in Python, JavaScript, Go, Java, C#, and Rust, you will build complete RAG pipelines integrated with LangChain, LlamaIndex, Haystack, and a wide range of embedding providers. This is not a tutorial collection; it is a comprehensive reference that explains the why behind every feature, the trade-offs between every configuration choice, and the production engineering practices that separate experimental prototypes from systems serving millions of queries per day.

Bundles

Bundles that include this book

Author

About the Author

Steve Publications

Steve is a technology professional with more than 20 years of experience spanning software development, server infrastructure, cybersecurity, vulnerability research and reverse engineering. His work focuses on understanding complex systems, uncovering security weaknesses and developing practical solutions that make technology more secure, reliable and effective.

Through Steve Publications, he collaborates with experienced researchers, engineers and industry experts to create practical, technically rigorous books on various topics not limited to self-improvement, software development, cybersecurity, cloud computing, DevOps, artificial intelligence and enterprise technologies. His mission is to make complex technical subjects accessible through clear explanations, real-world examples and hands-on exercises that help IT professionals, students and technology enthusiasts build valuable, practical skills.

Steve Publications embraces AI as a supporting tool for translation, proofreading and editorial refinement, not as a substitute for original research, technical expertise, or hands-on experience. Some contributors choose to publish under pseudonyms to protect their privacy or maintain professional boundaries.

Behind every book is a commitment to technical accuracy, practical relevance and continuous improvement. Our publications are written, reviewed and maintained by experienced professionals, with support from a private community of more than 420 engineers and researchers. Rather than prioritizing volume or mass-produced AI-generated content, we focus on delivering reliable, useful resources that readers can apply in real-world environments.

We also welcome experienced professionals who want to share their knowledge by writing or reviewing books, particularly in specialized and emerging technology fields. If you have expertise to contribute, we invite you to get in touch and explore opportunities to collaborate.

Our commitment is simple: To deliver books that respect our readers' time, support their professional growth and provide lasting practical value. If a book does not meet your expectations, Leanpub offers a 60-day money-back guarantee.

Contents

Table of Contents

Building Production Vector Search Systems with the Open-Source Vector Database

Introduction: The Retrieval Problem

  1. What This Book Covers
  2. Who This Book Is For
  3. How to Use This Book

Chapter 1: The Vector Revolution – Why RAG Needs Better Than SQL

  1. From Keywords to Meaning: The Limits of Text Search
  2. What Are Embeddings? A Practical Understanding
  3. Similarity Search at Scale: The Core Challenge
  4. The Rise of Retrieval-Augmented Generation
  5. Why Purpose-Built Vector Databases Matter

Chapter 2: Anatomy of a RAG System

  1. The RAG Pipeline End to End
  2. Document Ingestion: Chunking Strategies and Trade-offs
  3. Embedding Models: Selection, Dimensions and Quality
  4. The Retrieval Layer: Search, Reranking and Fusion
  5. Generation: Feeding Context to LLMs Effectively
  6. Evaluation Metrics for RAG Systems

Chapter 3: Meet Qdrant – Design Philosophy and Architecture

  1. The Story Behind Qdrant: Origins and Open Source Vision
  2. Core Data Model: Collections, Points, Vectors and Payloads
  3. Internal Architecture: Storage Engine and Indexing Pipeline
  4. HNSW at Scale: How Qdrant’s Approximate Nearest Neighbor Works
  5. Performance Characteristics: Latency, Throughput and Memory

Chapter 4: Getting Started – Installation and First Steps

  1. Running Qdrant Locally with Docker
  2. Native Binary Installation for Production
  3. The REST API: Your First Collection and Points
  4. Python Client: Installation and Basic Operations
  5. Quick Start: A Complete Embedding and Search Example
  6. Common Configuration Options Explained

Chapter 5: Collections, Vectors and Payloads – The Data Model Deep Dive

  1. Creating and Configuring Collections
  2. Vector Types: Dense, Sparse, Multi-Dimensional and Multi-Vectors
  3. Distance Metrics: Cosine, Euclidean, Dot Product – When to Use Which
  4. Payloads: Structured Metadata for Filtering and Faceting
  5. Schema Design Patterns for RAG Applications

Chapter 6: Indexing Strategies – HNSW, Quantization and Optimization

  1. HNSW Parameters: m, ef_construction and Their Impact
  2. Vector Indexes vs. Flat Search: Accuracy-Speed Trade-offs
  3. Quantization: Binary, Scalar, Product Quantization Explained
  4. Payload Indexing: Types, Selectivity and Query Plans
  5. Performance Tuning: Memory, Disk and CPU Considerations

Chapter 7: Searching – Similarity, Filtered and Hybrid Retrieval

  1. Basic Similarity Search: Nearest Neighbors and Pagination
  2. Filtered Search: Match, Range, Geo and Nested Filters
  3. Hybrid Search: Combining Dense and Sparse Vectors
  4. Recommend API: Content-Based Recommendations
  5. Group Search and Diversified Results
  6. Search Performance Patterns and Anti-Patterns

Chapter 8: Building Complete RAG Pipelines with Qdrant

  1. Document Processing Pipeline: Chunking and Embedding
  2. Batch Ingestion Strategies for Large Corpora
  3. Retrieval with Filtering: Query-Time Metadata Constraints
  4. Reranking: Cross-Encoders and Learning-to-Rank
  5. Caching Strategies for Cost and Latency Reduction
  6. Complete RAG Application: From Documents to Answers

Chapter 9: Integrations – LangChain, LlamaIndex, Haystack and Beyond

  1. LangChain Integration: Vector Stores and Retrievers
  2. LlamaIndex Integration: Indexes and Query Engines
  3. Haystack Integration: Document Stores and Pipelines
  4. OpenAI and OpenAI-Compatible Embedding Providers
  5. Hugging Face Transformers and Sentence Transformers
  6. Custom Integrations: Building Your Own Connectors

Chapter 10: Advanced Integrations – Multi-Language and Framework Support

  1. JavaScript and TypeScript Client: Node.js and Browser Usage
  2. Go Client: High-Performance Server-Side Integration
  3. Java Client: Enterprise Application Integration
  4. C# Client: .NET Ecosystem Support
  5. Rust Client: Systems-Level Performance

Chapter 11: Distributed Deployments – Sharding, Replication and Clustering

  1. Shard Architecture: Local vs. Remote Shards
  2. Replication Strategies and Quorum Configuration
  3. Cluster Topology and Node Management
  4. Over-the-Air Updates and Rolling Restarts
  5. Disaster Recovery: Snapshots, Backups and Restore Procedures

Chapter 12: Security, Authentication and Access Control

  1. API Key Authentication: Setup and Management
  2. JWT-Based Authentication for Fine-Grained Access
  3. TLS/SSL Configuration for Encrypted Communication
  4. Network Security: Firewalls, Proxies and Private Networks
  5. Production Hardening Checklist

Chapter 13: Monitoring, Observability and Operations

  1. Metrics and the Prometheus Exporter
  2. Key Performance Indicators for Vector Search
  3. Logging Configuration and Debugging Techniques
  4. Health Checks and Readiness Probes
  5. Operational Runbooks: Common Issues and Resolutions

Chapter 14: Scaling to Billions – Architecture Patterns for Massive Scale

  1. Capacity Planning: How Many Vectors Can Qdrant Handle?
  2. Multi-Cluster Architectures and Federation Patterns
  3. Read Replicas and Write Optimization Strategies
  4. Data Lifecycle: TTL, Archival and Pruning
  5. Cost-Performance Analysis: Hardware Sizing and Cloud Economics

Chapter 15: Qdrant vs. the Competition – Choosing the Right Vector Database

  1. Comparison Framework: What Matters in a Vector Database
  2. Qdrant vs. Milvus: Scale and Complexity
  3. Qdrant vs. Weaviate: GraphQL vs. REST
  4. Qdrant vs. Chroma: Simplicity vs. Production Readiness
  5. Qdrant vs. pgvector: Embedded vs. Standalone
  6. Qdrant vs. Pinecone: Open Source vs. Managed Service
  7. Qdrant vs. Elasticsearch and FAISS: Different Paradigms
  8. Summary Comparison Matrix

Chapter 16: Migration, Schema Evolution and Future-Proofing

  1. Migrating from Other Vector Databases to Qdrant
  2. Schema Evolution: Adding Fields, Changing Distance Metrics
  3. Zero-Downtime Upgrades and Version Compatibility
  4. Handling Breaking Changes Gracefully
  5. Future-Proofing Your RAG Infrastructure

Conclusion: The State of the Art and What Comes Next

  1. What Makes Qdrant Distinctive
  2. Where Vector Search Is Heading
  3. The Engineer’s Responsibility

References

Get the free sample chapters

Click the buttons to get the free sample in PDF or EPUB, or read the sample online here

The Leanpub 60 Day 100% Happiness Guarantee

Within 60 days of purchase you can get a 100% refund on any Leanpub purchase, in two clicks.

See full terms...

Earn $8 on a $10 Purchase, and $16 on a $20 Purchase

We pay 80% royalties on purchases of $7.99 or more, and 80% royalties minus a 50 cent flat fee on purchases between $0.99 and $7.98. You earn $8 on a $10 sale, and $16 on a $20 sale. So, if we sell 5000 non-refunded copies of your book for $20, you'll earn $80,000.

(Yes, some authors have already earned much more than that on Leanpub.)

Learn more about writing on Leanpub

Free Updates. DRM Free.

If you buy a Leanpub book, you get free updates for as long as the author updates the book! Many authors use Leanpub to publish their books in-progress, while they are writing them. All readers get free updates, regardless of when they bought the book or how much they paid (including free).

Most Leanpub books are available in PDF (for computers) and EPUB (for phones, tablets and Kindle). The formats that a book includes are shown at the top right corner of this page.

Finally, Leanpub books don't have any DRM copy-protection nonsense, so you can easily read them on any supported device.

Learn more about Leanpub's ebook formats and where to read them

Write and Publish on Leanpub

You can use Leanpub to easily write, publish and sell in-progress and completed ebooks and online courses!

Leanpub is a powerful platform for serious authors, combining a simple, elegant writing and publishing workflow with a store focused on selling in-progress ebooks.

Leanpub is a magical typewriter for authors: just write in plain text, and to publish your ebook, just click a button. (Or, if you are producing your ebook your own way, you can even upload your own PDF and/or EPUB files and then publish with one click!) It really is that easy.

Learn more about writing on Leanpub