Natural Language Processing
I have been working in the field of Natural Language Processing (NLP) since 1985 so I ‘lived through’ the revolutionary change in NLP that has occurred since 2014: deep learning results out-classed results from previous symbolic methods.
We won’t be using Large Language Models (LLMs) in this chapter; we cover LLMs in several chapters later in this book. Here we use the spaCy NLP library that is simple to use and provides good results.
I will not cover older symbolic methods of NLP here, rather I refer you to my previous books Practical Artificial Intelligence Programming With Java, Loving Common Lisp, or The Savvy Programmer’s Secret Weapon, and Haskell Tutorial and Cookbook for examples. We get better results using Deep Learning (DL) for NLP and the library spaCy (https://spacy.io) that we use in this chapter provides near state-of-the-art performance. The authors of spaCy frequently update it to use the latest breakthroughs in the field.
You will learn how to apply both DL and NLP by using the state-of-the-art full-feature library spaCy. This chapter concentrates on how to use spaCy in the Hy language for solutions to a few selected problems in NLP that I use in my own work. I urge you to also review the “Guides” section of the spaCy documentation where examples are in Python but after experimenting with the examples in this chapter you should have no difficulty in translating any spaCy Python examples to the Hy language.
The uv project in source_code_for_examples/nlp declares both the spaCy library and its small English language model en_core_web_sm as dependencies. The model is not published on PyPI, so pyproject.toml tells uv where to download the model’s wheel file:
1 dependencies = [
2     "hy>=1.3.1",
3     "pytest>=9.2.0",
4     "spacy>=3.8.7",
5     "en-core-web-sm",
6 ]
7
8 [tool.uv.sources]
9 en-core-web-sm = { url = "https://github.com/explosion/spacy-models/releases/download/en_core_web_sm-3.8.0/en_core_web_sm-3.8.0-py3-none-any.whl" }
You may see older instructions that install the model with python -m spacy download en_core_web_sm. Don’t do that in a uv project: the next uv sync (which uv run performs automatically) removes any package that is not declared in pyproject.toml, so the model would silently disappear. Setup is just:
1 $ cd hy-lisp-python-book/source_code_for_examples/nlp
2 $ uv sync
Exploring the spaCy Library
We will use the Hy REPL to experiment with spaCy, Lisp style. The following REPL listings are all from the same session, split into separate listings so that I can talk you through the examples:
 1 $ uv run hy
 2 Hy 1.3.1 (Eyes in the Sky) using CPython(main) 3.14.7 on Darwin
 3 => (import spacy)
 4 => (setv nlp-model (spacy.load "en_core_web_sm"))
 5 => (setv doc (nlp-model "President George Bush went to Mexico and he had a very good meal"))
 6 => doc
 7 President George Bush went to Mexico and he had a very good meal
 8 => (type doc)
 9 <class 'spacy.tokens.doc.Doc'>
10 => (lfor x (dir doc) :if (not (.startswith x "_")) x)
11 ['cats', 'char_span', 'copy', 'count_by', 'doc', 'ents', 'extend_tensor', 'from_array', 'from_bytes', 'from_dict', 'from_disk', 'from_docs', 'from_json', 'get_extension', 'get_lca_matrix', 'has_annotation', 'has_extension', 'has_unknown_spaces', 'has_vector', 'is_nered', 'is_parsed', 'is_sentenced', 'is_tagged', 'lang', 'lang_', 'mem', 'noun_chunks', 'noun_chunks_iterator', 'remove_extension', 'retokenize', 'sentiment', 'sents', 'set_ents', 'set_extension', 'similarity', 'spans', 'tensor', 'text', 'text_with_ws', 'to_array', 'to_bytes', 'to_dict', 'to_disk', 'to_json', 'to_utf8_array', 'user_data', 'user_hooks', 'user_span_hooks', 'user_token_hooks', 'vector', 'vector_norm', 'vocab']
In lines 3-5 we import the spaCy library, load the English language model, and create a document from input text. What is a spaCy document? Line 9 shows that it is an instance of the class Doc. In line 10 we use the standard Python function dir to list the names defined for the object doc. The unfiltered output of dir starts with many built in “dunder” (double underscore) attributes and private names, so we use lfor with an :if clause to keep only the names that do not start with an underscore.
The to_json method looks promising (in Hy we can call it as .to-json), so we will import the Python pretty print library and look at the pretty printed result of calling it on our document stored in doc. The result is large, so we look at it one key at a time:
 1 => (import pprint [pprint])
 2 => (setv j (doc.to-json))
 3 => (list (.keys j))
 4 ['text', 'ents', 'sents', 'tokens']
 5 => (pprint (get j "ents"))
 6 [{'end': 21, 'label': 'PERSON', 'start': 10},
 7  {'end': 36, 'label': 'GPE', 'start': 30}]
 8 => (pprint (cut (get j "tokens") 0 2))
 9 [{'dep': 'compound',
10   'end': 9,
11   'head': 2,
12   'id': 0,
13   'lemma': 'President',
14   'morph': 'Number=Sing',
15   'pos': 'PROPN',
16   'start': 0,
17   'tag': 'NNP'},
18  {'dep': 'compound',
19   'end': 16,
20   'head': 2,
21   'id': 1,
22   'lemma': 'George',
23   'morph': 'Number=Sing',
24   'pos': 'PROPN',
25   'start': 10,
26   'tag': 'NNP'}]
27 =>
The JSON data is nested dictionaries. In a later chapter on Knowledge Graphs, we will want to get the named entities like people, organizations, etc., from text and use this information to automatically generate data for Knowledge Graphs. The value for the key ents (lines 17-18) identifies each entity by its starting and ending character offsets in the text, plus an entity type label.
Each entry for the key tokens (we print the first two on lines 20-37) contains the starting and ending character offsets, the token number (id), the token number of its syntactic head in the dependency parse, the dependency label (dep), the base form of the word (lemma), morphological features (morph), and both the coarse (pos) and fine grained (tag) part of speech. We list what the parts of speech mean later.
We would like the words for each entity to be concatenated into a single string for each entity. The ents attribute of the document already gives us entity spans, so in lines 41-44 we print the text and label of each one. I like to add the entity name strings back into the dictionary representing a document, and line 45 shows the use of lfor to create a list of lists where the sublists contain the entity name as a single string and the type of entity. We list the entity types later in this chapter.
1 => doc.ents
2 (George Bush, Mexico)
3 => (for [entity doc.ents]
4 ...   (print "entity text:" entity.text "entity label:" entity.label_))
5 entity text: George Bush entity label: PERSON
6 entity text: Mexico entity label: GPE
7 => (lfor entity doc.ents [entity.text entity.label_])
8 [['George Bush', 'PERSON'], ['Mexico', 'GPE']]
9 =>
We can also access each sentence as a separate span. In this example the original text used to create our sample document had only a single sentence so the sents property returns a list containing a single sentence:
1 => (list doc.sents)
2 [President George Bush went to Mexico and he had a very good meal]
3 =>
The last example showing how to use a spaCy document object is listing each word with its part of speech and lemma (dictionary form). Notice the lemmas “go” for “went” and “have” for “had”:
 1 => (for [word doc]
 2 ...   (print word.text word.pos_ word.lemma_))
 3 President PROPN President
 4 George PROPN George
 5 Bush PROPN Bush
 6 went VERB go
 7 to ADP to
 8 Mexico PROPN Mexico
 9 and CCONJ and
10 he PRON he
11 had VERB have
12 a DET a
13 very ADV very
14 good ADJ good
15 meal NOUN meal
16 =>
The following list shows the definitions for the part of speech (POS) tags:
- ADJ: adjective
- ADP: adposition
- ADV: adverb
- AUX: auxiliary verb
- CONJ: coordinating conjunction
- DET: determiner
- INTJ: interjection
- NOUN: noun
- NUM: numeral
- PART: particle
- PRON: pronoun
- PROPN: proper noun
- PUNCT: punctuation
- SCONJ: subordinating conjunction
- SYM: symbol
- VERB: verb
- X: other
Implementing a HyNLP Wrapper for the Python spaCy Library
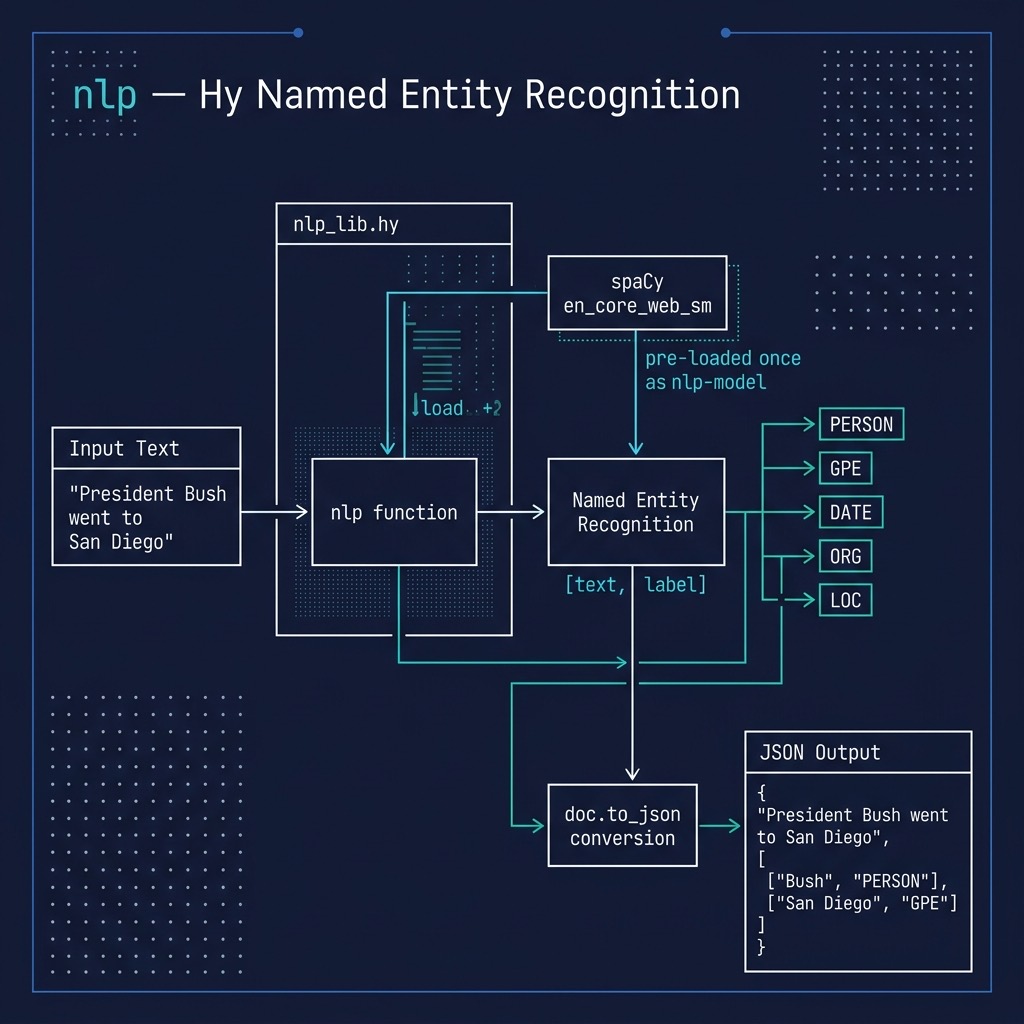
The wrapper library is in the file nlp_lib.hy and a short example program that uses it is in the file nlp_example.hy.
For an example in a later chapter, we will use the library developed here to automatically generate Knowledge Graphs from text data. We will need the ability to find person, company, location, etc. names in text. We use spaCy here to do this. The types of named entities on which spaCy is pre-trained includes:
- CARDINAL: any number that is not identified as a more specific type, like money, time, etc.
- DATE
- FAC: facilities like highways, bridges, airports, etc.
- GPE: Countries, states (or provinces), and cities
- LOC: any non-GPE location
- PRODUCT
- EVENT
- LANGUAGE: any named language
- MONEY: any monetary value or unit of money
- NORP: nationalities or religious groups
- ORG: any organization like a company, non-profit, school, etc.
- PERCENT: any number in
 followed by the percent % character
- PERSON
- ORDINAL: any number spelled out, like “one”, “two”, etc.
- TIME
Listing for source_code_for_examples/nlp/nlp_lib.hy:
 1 ;; NLP (Named Entity Recognition) library for Hy, a thin wrapper around spaCy.
 2
 3 (import spacy)
 4
 5 ;; Load the small pretrained English spaCy model once, when this module is
 6 ;; first imported, and reuse it for every call to nlp.
 7 (setv nlp-model (spacy.load "en_core_web_sm"))
 8
 9 (defn nlp [some-text]
10   "Analyze SOME-TEXT with spaCy and return a dictionary (spaCy's JSON-style
11   document representation) containing:
12     \"text\"     - the original input text
13     \"tokens\"   - token data: character offsets, part of speech, dependency, etc.
14     \"sents\"    - sentence boundaries
15     \"ents\"     - spaCy's entity records (character offsets and label)
16     \"entities\" - the same entities as simple [entity-text entity-type] pairs,
17                  where the type is a spaCy label such as PERSON, GPE, or ORG."
18   (setv doc (nlp-model some-text))
19   (setv j (doc.to-json))
20   ;; Add the entities as simple [text type] pairs, which are easier to use
21   (setv (get j "entities") (lfor entity doc.ents [entity.text entity.label_]))
22   j)
The spaCy model is loaded once, on line 7, when the module is first imported; loading takes a moment, so we do not want to repeat it for every call. The function nlp returns spaCy’s JSON-style dictionary for the document, with an added entities key (line 21) holding the simpler list of [text type] pairs we built in the REPL session.
Listing for source_code_for_examples/nlp/nlp_example.hy:
 1 ;; Demonstrates the nlp function from nlp_lib.hy: named entity recognition.
 2
 3 (import nlp-lib [nlp])
 4
 5 (defn main []
 6   (for [text ["President George Bush went to Mexico and he had a very good meal"
 7               "Lucy threw a ball to Bill and he caught it"]]
 8     (print "Text:    " text)
 9     (print "Entities:" (get (nlp text) "entities"))
10     (print)))
11
12 (when (= __name__ "__main__")
13   (main))
Here is the output:
1 $ uv run hy nlp_example.hy
2 Text:     President George Bush went to Mexico and he had a very good meal
3 Entities: [['George Bush', 'PERSON'], ['Mexico', 'GPE']]
4
5 Text:     Lucy threw a ball to Bill and he caught it
6 Entities: [['Lucy', 'PERSON'], ['Bill', 'PERSON']]
The tests in test_nlp_lib.hy run these same sentences through nlp and check the entities, tokens, and output of main. Run them with uv run pytest.
Wrap-up
I spent several years of development time during the period from 1984 through 2015 working on natural language processing technology and as a personal side project I sold commercial NLP libraries that I wrote on my own time in Ruby and Common Lisp. The state-of-the-art of Deep Learning enhanced NLP is very good and the open source spaCy library makes excellent use of both conventional NLP technology and pre-trained Deep Learning models. I no longer spend very much time writing my own NLP libraries and instead use spaCy or more recently LLMs that we cover later.
I urge you to read through the spaCy documentation because we covered just basic functionality here that we will also need in the later chapter on automatically generating data for Knowledge Graphs. After working through the interactive REPL sessions and the examples in this chapter, you should be able to translate any Python API example code to Hy.
Optional Practice Problems
Here are a few optional practice problems to help you get more comfortable with spaCy and the Hy language. We encourage you to modify the code in the source_code_for_examples/nlp directory and experiment!
Problem 1: Filter Entities by Type
Currently, the nlp function in nlp_lib.hy returns all recognized entities. Modify the function (or write a new one) that takes an optional list of allowed entity labels (e.g., ["PERSON", "ORG"]) and filters the results.
- Implement the filtering logic in nlp_lib.hy.
- Update nlp_example.hy to call this function and only print entities of type
"PERSON". - Tip: You can use Hy’s list comprehensions (
lfor) and check if an entity’s label is in the list of allowed labels using theinoperator.
Problem 2: Extract Noun Phrases (Noun Chunks)
In addition to named entities, spaCy is excellent at identifying noun chunks (base noun phrases).
- Read the spaCy documentation for
doc.noun_chunksor inspect it using the Hy REPL. - Add a new function
get-noun-chunksto nlp_lib.hy that processes input text and returns a list of strings representing the noun chunks. - Verify your implementation in nlp_example.hy by analyzing a sentence like
"The quick brown fox jumps over the lazy dog".
Problem 3: Token Filtering (Removing Stopwords and Punctuation)
When preparing text for downstream machine learning tasks, it is common to filter out punctuation and stopwords (common words like “the”, “is”, “at”).
- Inspect the attributes of a spaCy token in the REPL (e.g.,
word.is_punctandword.is_stop). - Write a function
clean-text-tokensin nlp_lib.hy that returns a list of token text strings, excluding any tokens whereword.is_punctorword.is_stopis true. - Test your function with a sample sentence and ensure the output contains only meaningful content words.