Running Local LLMs Using Ollama
We saw in previous chapters how to use LLMs from commercial providers, for example GPT-5 from OpenAI and Gemini from Google. Here we run smaller models on our own laptops or servers. You need to install Ollama: https://ollama.com.
The examples for this chapter are in the directory hy-lisp-python-book/source_code_for_examples/ollama_examples.
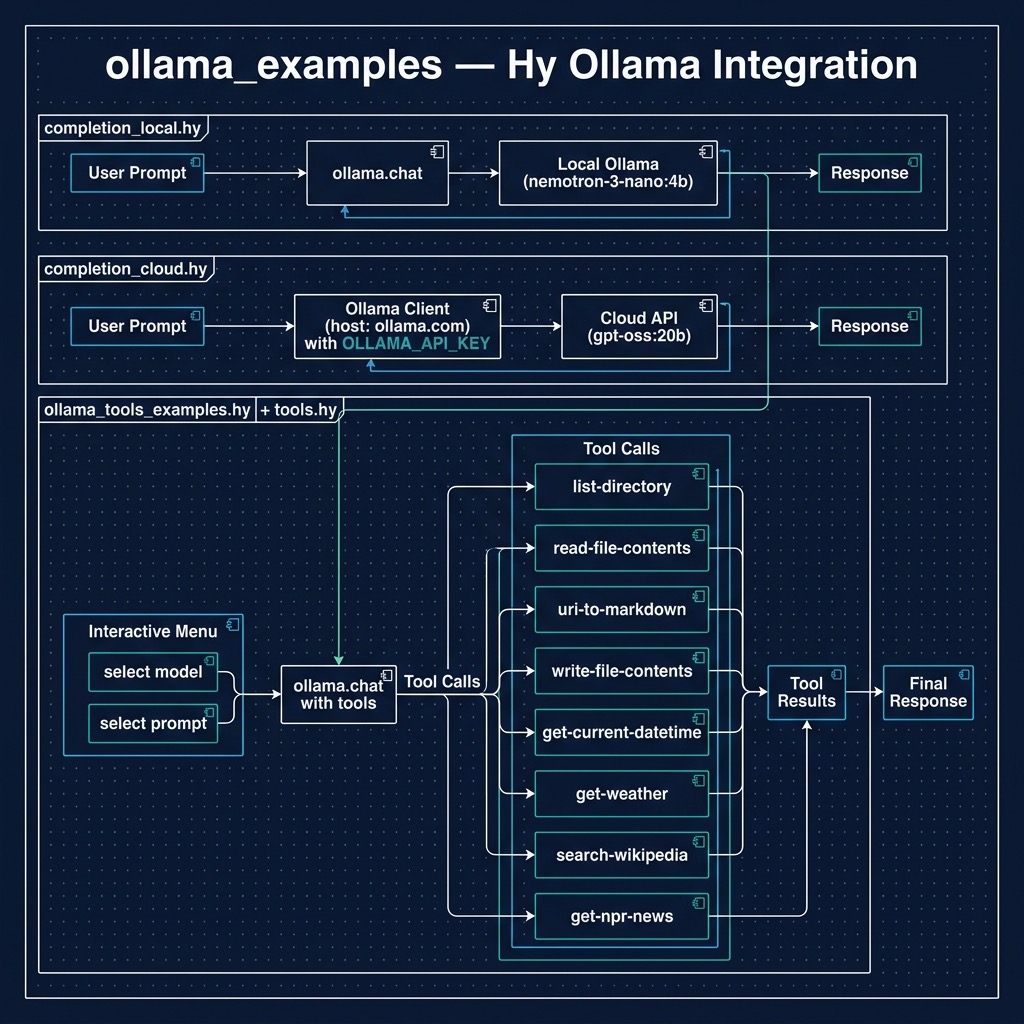
Install Ollama and then download a model we will experiment with:
1 $ ollama pull nemotron-3-nano:4b
2 $ ollama serve
The first line is run one time to download a model. The second line is run whenever you want to call the local Ollama service.
Ollama also provides a cloud service that can be used for occasional experiments for free. Examples in this chapter work with local models and if you sign up to get an API key and set the environment variable OLLAMA_API_KEY to your key then you can experiment also with the cloud examples.
Completions
Here we look at a “hello world” type simple example: we pass a text prompt to a local Ollama server instance. This is similar to previous examples for GPT-5 and Gemini.
The example code is in the file completion_local.hy and uses a local model:
 1 (import os)
 2 (import ollama)
 3
 4 ;; Set OLLAMA_MODEL to use a different local model
 5 (setv model (os.environ.get "OLLAMA_MODEL" "nemotron-3-nano:4b"))
 6
 7 (defn completion [prompt]
 8   ;; Initiate chat with the model
 9   (setv response
10         (ollama.chat
11           :model model
12           :messages [{"role" "user" "content" prompt}]))
13   response.message.content)
14
15 ;;;; Test code:
16
17 ;; User prompt
18 (setv
19   user-prompt
20   "Sally is 77, Bill is 32, and Alex is 44 years old. Pairwise, what are their age differences? Be concise."
21   )
22
23 (when (= __name__ "__main__")
24   (print
25    (completion user-prompt)))
The model name is read from the environment variable OLLAMA_MODEL, defaulting to the model we pulled above, so you can try any other local model with, for example, OLLAMA_MODEL=qwen3.5:4b uv run hy completion_local.hy. The output looks like:
1 $ uv run hy completion_local.hy
2 Using CPython 3.12.12
3 Creating virtual environment at: .venv
4 Installed 18 packages in 10ms
5 Sally-Bill: 45 years
6 Sally-Alex: 33 years
7 Bill-Alex: 12 years
Cloud Model Completion Example
If you set the environment variable OLLAMA_API_KEY then you can also use the example completion_cloud.hy, which connects directly to Ollama’s cloud service and sends the key as a standard Bearer token in the Authorization header:
 1 ; Ensure OLLAMA_API_KEY is set in ENV
 2
 3 (import os)
 4 (import ollama [Client])
 5
 6 ; Create client for Ollama Cloud API
 7 (setv client
 8   (Client
 9     :host "https://ollama.com"
10     :headers {"Authorization" (+ "Bearer " (.get os.environ "OLLAMA_API_KEY" ""))}))
11
12 (defn completion [prompt]
13   "Generate a completion using the Ollama Cloud API"
14   (setv response
15         (client.chat
16           "gpt-oss:20b"
17           :messages [{"role" "user" "content" prompt}]
18           :stream False))
19   (get (get response "message") "content"))
20
21 ;;;; Test code:
22
23 ; User prompt
24 (setv
25   user-prompt
26   "Sally is 77, Bill is 32, and Alex is 44 years old. Pairwise, what are their age differences? Be concise."
27   )
28
29 (when (= __name__ "__main__")
30   (print
31    (completion user-prompt)))
Tool Use
In the context of this book using tools means that we define functions in the Hy language and configure a Large Language Model to use these tools.
The example for this section ollama_tools_examples.hy works with local models and also cloud models if you have OLLAMA_API_KEY set. This example will show you a list of all available models (locally downloaded and any cloud models where you have pulled a tiny stub using, for example ollama pull deepseek-v3.1:671b-cloud) and you can select any model, then select from a list of prompts designed to test all tools defined in the file tools.hy.
Integrating tool use with Ollama represents a pivotal step in the evolution of local AI, bridging the gap between offline language models and interactive, real-world applications. This capability, often referred to as function calling, allows LLMs running on your own hardware to execute external code and query APIs, breaking the confines of their static training data. By equipping a local model with tools, developers can empower applications using LLMs to, for example, fetch live weather data, search a database, or control other software services. This transforms the LLM from a simple text-generation engine into a dynamic agent capable of performing complex, multi-step tasks and interacting directly with its environment, all while maintaining the privacy and control inherent to the Ollama ecosystem.
Use of Python docstrings at runtime: the Ollama Python SDK leverages docstrings as a crucial part of its runtime function calling mechanism. When defining functions that will be called by the LLM, the docstrings serve as structured metadata that gets parsed and converted into a JSON schema format. This schema describes the function’s parameters, their types, and expected behavior, which is then used by the model to understand how to properly invoke the function. The docstrings follow a specific format that includes parameter descriptions, type hints, and return value specifications, allowing the SDK to automatically generate the necessary function signatures that the LLM can understand and work with.
During runtime execution, when the LLM determines it needs to call a function, it first reads these docstring-derived schemas to understand the function’s interface. The SDK parses these docstrings using Python’s introspection capabilities (through the inspect module) and matches the LLM’s intended function call with the appropriate implementation. This system allows for a clean separation between the function’s implementation and its interface description, while maintaining human-readable documentation that serves as both API documentation and runtime function calling specifications. The docstring parsing is done lazily at runtime when the function is first accessed, and the resulting schema is typically cached to improve performance in subsequent calls.
Here is the sample tools library defined in tools.hy. This implementation defines a suite of functional tools designed for Large Language Model (LLM) orchestration, specifically tailored for the Ollama ecosystem. By leveraging Hy’s symbolic expression syntax, the code provides a clean, declarative approach to common side-effect operations such as filesystem manipulation, network requests, and data transformation. The module imports standard Python libraries like os, httpx, and xml.etree.ElementTree alongside third-party utilities like markdownify, demonstrating how seamlessly Hy bridges the gap between functional programming paradigms and the vast Python ecosystem. Each function ranging from directory listing and file I/O to real-time weather fetching and NPR news aggregation—is structured with clear docstrings and metadata, making them ideal candidates for “Function Calling” or “Tool Use” within an agentic LLM framework where the model must interact with the external world to fulfill complex user queries.
  1 ;; Tool functions that an LLM can call through the Ollama Python SDK.
  2 ;;
  3 ;; The SDK builds each tool's description for the model from the function's
  4 ;; name and docstring, including the "Args:" section, so the docstrings below
  5 ;; are part of the program, not just documentation.
  6
  7 (import os)
  8 (import pathlib [Path])
  9 (import httpx)
 10 (import markdownify [markdownify])
 11 (import datetime [datetime])
 12 (import xml.etree.ElementTree :as ET)
 13
 14 (setv http-headers {"User-Agent" "HyLangBook-OllamaTools/1.0"})
 15 (setv timeout 20)   ; seconds to wait for any web request
 16
 17 (defn safe-path [file-path]
 18   "Resolve FILE-PATH and make sure it is inside the current directory.
 19   The model chooses the paths passed to the file tools, so we never let it
 20   read or write files elsewhere on the computer."
 21   (setv base (.resolve (Path.cwd)))
 22   (setv path (.resolve (/ base file-path)))
 23   (when (not (.is-relative-to path base))
 24     (raise (PermissionError f"{file-path} is outside the working directory")))
 25   path)
 26
 27 (defn list-directory []
 28   "Lists files and directories in the current working directory.
 29
 30   Returns:
 31     A string containing the current directory name and the files in it.
 32   "
 33   (setv current-dir (os.path.realpath "."))
 34   f"Contents of current directory {current-dir} is: {(sorted (os.listdir current-dir))}")
 35
 36 (defn read-file-contents [file-path]
 37   "Reads the contents of a file in the current working directory.
 38
 39   Args:
 40     file-path: The path to the file, relative to the working directory.
 41
 42   Returns:
 43     The contents of the file as a string.
 44   "
 45   (.read-text (safe-path file-path) :encoding "utf-8"))
 46
 47 (defn write-file-contents [file-path content]
 48   "Writes text to a file in the current working directory.
 49
 50   Args:
 51     file-path: The path to the file, relative to the working directory.
 52     content: The text to write to the file.
 53
 54   Returns:
 55     A message confirming the write.
 56   "
 57   (.write-text (safe-path file-path) content :encoding "utf-8")
 58   f"Successfully wrote to {file-path}")
 59
 60 (defn uri-to-markdown [uri]
 61   "Fetches a web page and converts its HTML to Markdown.
 62
 63   Args:
 64     uri: The URL of the web page.
 65
 66   Returns:
 67     The page content as Markdown.
 68   "
 69   (setv response (httpx.get uri :headers http-headers :timeout timeout
 70                                 :follow-redirects True))
 71   (.raise-for-status response)
 72   f"# Content from {uri}\n\n{(markdownify response.text)}")
 73
 74 (defn get-current-datetime []
 75   "Returns the current system date and time.
 76
 77   Returns:
 78     The date and time formatted as YYYY-MM-DD HH:MM:SS.
 79   "
 80   (.strftime (datetime.now) "%Y-%m-%d %H:%M:%S"))
 81
 82 (defn get-weather [location]
 83   "Fetches a one-line summary of the current weather.
 84
 85   Args:
 86     location: A city or region name, for example London.
 87
 88   Returns:
 89     A short weather summary.
 90   "
 91   (setv response (httpx.get f"https://wttr.in/{location}?format=3"
 92                             :headers http-headers :timeout timeout))
 93   (.raise-for-status response)
 94   (.strip response.text))
 95
 96 (defn search-wikipedia [query]
 97   "Returns the introductory summary paragraph of a Wikipedia article.
 98
 99   Args:
100     query: The title of the Wikipedia article to look up.
101
102   Returns:
103     The article summary, or a message saying it was not found.
104   "
105   (setv url (+ "https://en.wikipedia.org/api/rest_v1/page/summary/"
106                (.replace query " " "_")))
107   (setv response (httpx.get url :headers http-headers :timeout timeout
108                                 :follow-redirects True))
109   (if (= response.status-code 200)
110       (get (.json response) "extract")
111       f"Failed to fetch Wikipedia page for {query}"))
112
113 (defn get-npr-news []
114   "Fetches the top news headlines and summaries from NPR's public RSS feed.
115
116   Returns:
117     The first five headlines with links and summaries, as Markdown.
118   "
119   (setv response (httpx.get "https://feeds.npr.org/1001/rss.xml"
120                             :headers http-headers :timeout timeout))
121   (.raise-for-status response)
122   (setv items (cut (.findall (ET.fromstring response.text) "./channel/item") 5))
123   (setv news-md "# NPR Top News\n\n")
124   (for [item items]
125     (setv [title link desc] (gfor tag ["title" "link" "description"]
126                                   (. (.find item tag) text)))
127     (+= news-md f"## [{title}]({link})\n{desc}\n\n"))
128   news-md)
Notice that the parameter descriptions are in each function’s docstring under an Args: heading. The Ollama SDK parses these Google-style docstrings to build the JSON schema that describes each tool to the model, so a clear docstring directly improves how well the model uses a tool.
The file tools deserve special care. The model, not you, chooses the file paths they receive, and a model can be confused or manipulated by text in a web page it reads (a prompt injection). The function safe-path resolves each path and raises a PermissionError if it would point outside the current working directory, so the model cannot read or overwrite files such as your SSH keys. Every web request also has a timeout. The tests in test_ollama_examples.hy check that paths like ../secret.txt and /etc/passwd are rejected.
The code demonstrates a robust pattern for extending LLM capabilities through external API integrations and local system access. Functions like search-wikipedia and get-npr-news showcase how to handle HTTP headers and parse varied data formats, such as JSON and RSS/XML, converting the raw results into Markdown strings that are easily digestible by an LLM’s context window. The use of the httpx library ensures efficient, modern synchronous requests, while the integration of markdownify in the uri-to-markdown function helps strip away the “noise” of HTML tags, leaving only the semantic content for the model to process.
From a structural standpoint, these tools are built to be self-contained and modular. Each function follows a predictable “Input-Process-Output” flow, returning string-based feedback that can be piped directly back into a LLM chat completion loop. By providing the model with access to the list-directory and read-file-contents utilities, you effectively give the AI a “workspace” to explore and analyze, while the get-current-datetime function solves the common LLM limitation regarding temporal awareness. This collection serves as a practical blueprint for building any Hy language based agent that requires more than just static training data to provide accurate, real-time assistance.
In the next example in file ollama_tools_examples.hy we will configure a LLM to call the tools (or functions) defined in the last code listing. Note that this example works with both local and Ollama Cloud models.
This script provides a practical test harness for evaluating “Tool Use” or “Function Calling” capabilities across different models hosted on a local Ollama instance and also Ollama Cloud. By importing the toolset defined in the previous section, the program establishes a dynamic environment where an LLM can choose to execute specific Hy functions based on the user’s natural language input. The implementation features a sophisticated model selection loop that filters for cloud-based or local models depending on the presence of an OLLAMA_API_KEY, followed by an interactive menu of predefined prompts designed to exercise various tool categories. By bridging the gap between a high level client.chat call and the execution of local Hy logic, this code demonstrates how to effectively close the loop in an agentic workflow: identifying the model’s intent to use a tool, dispatching that intent to a Python-backed function, and surfacing the result back to the console.
 1 ;; Interactive demo of LLM tool use with Ollama. Works with local models and,
 2 ;; if OLLAMA_API_KEY is set, with Ollama cloud models routed through your
 3 ;; local Ollama server.
 4
 5 (import os)
 6 (import ollama [Client])
 7 (import tools [list-directory read-file-contents uri-to-markdown
 8                write-file-contents get-current-datetime get-weather
 9                search-wikipedia get-npr-news])
10
11 (setv api-key (.get os.environ "OLLAMA_API_KEY"))
12 (setv client (Client :host "http://127.0.0.1:11434"))
13
14 ;; The functions the model may call, and a map from the (mangled) function
15 ;; names the model uses back to the Hy functions
16 (setv tool-functions [list-directory read-file-contents uri-to-markdown
17                       write-file-contents get-current-datetime get-weather
18                       search-wikipedia get-npr-news])
19 (setv available-functions (dfor f tool-functions f.__name__ f))
20
21 (setv prompts [
22   "List the files in the current directory."
23   "Read the content of 'pyproject.toml'."
24   "Convert 'https://en.wikipedia.org/wiki/Hy_(programming_language)' to markdown."
25   "Write 'Hello from Ollama tools!' to a file named 'test_output.txt'."
26   "What is the current date and time?"
27   "What is the weather in London?"
28   "Search Wikipedia for 'Lisp (programming language)' and give me a summary."
29   "What are the latest news headlines from NPR?"])
30
31 (defn get-available-models []
32   "Names of the models on the local Ollama server; cloud models are only
33   included when OLLAMA_API_KEY is set."
34   (try
35     (setv model-names (lfor m (. (client.list) models) m.model))
36     (if api-key
37         model-names
38         (lfor m model-names
39               :if (not (or (.endswith m ":cloud") (.endswith m "-cloud")))
40               m))
41     (except [e Exception]
42       (print "Error fetching models:" e)
43       [])))
44
45 (defn run-prompt [model user-prompt]
46   "Send USER-PROMPT to MODEL with our tools available. Run any tools the
47   model asks for and return a list of [tool-name result] pairs, or the
48   model's text answer if it did not call a tool."
49   (setv response (client.chat model
50                               :messages [{"role" "user" "content" user-prompt}]
51                               :tools tool-functions))
52   (if response.message.tool-calls
53       (lfor tool-call response.message.tool-calls
54             :setv name tool-call.function.name
55             :setv function (.get available-functions name)
56             [name (if function
57                       (function #** tool-call.function.arguments)
58                       f"Function {name} not found.")])
59       response.message.content))
60
61 (defn choose [prompt items]
62   "Print a numbered menu of ITEMS plus a final 'back/exit' choice and
63   return the chosen item, or None for the final choice."
64   (for [[i item] (enumerate items 1)]
65     (print f"{i}. {item}"))
66   (print f"{(+ (len items) 1)}. Back / Exit")
67   (while True
68     (setv answer (.strip (input prompt)))
69     (when (and (.isdigit answer) (<= 1 (int answer) (+ (len items) 1)))
70       (return (when (<= (int answer) (len items))
71                 (get items (- (int answer) 1)))))
72     (print "Please enter one of the numbers shown.")))
73
74 (defn main []
75   (while True
76     (setv models (get-available-models))
77     (when (not models)
78       (print "No models found. Is Ollama running? (ollama serve)")
79       (break))
80     (print "\n--- Available Models ---")
81     (setv model (choose "\nSelect a model (number): " models))
82     (when (is model None) (break))
83     (while True
84       (print f"\n--- Ollama Tools Test Menu (Model: {model}) ---")
85       (setv user-prompt (choose "\nSelect a prompt (number): " prompts))
86       (when (is user-prompt None) (break))
87       (print f"\n>>> Executing prompt: {user-prompt}\n")
88       (try
89         (setv result (run-prompt model user-prompt))
90         (if (isinstance result str)
91             (print f"Model Response: {result}")
92             (for [[name output] result]
93               (print f"Tool Call: {name}")
94               (print f"\n** Output of {name}: {output}")))
95         (except [e Exception]
96           (print f"\nError during execution: {e}"))))))
97
98 (when (= __name__ "__main__")
99   (main))
The architectural core of this script lies in the function run-prompt and the available-functions mapping. We pass the Hy functions themselves in the :tools list; the SDK reports their Python names, so a dfor builds available-functions from each function’s __name__ (Hy’s read-file-contents is read_file_contents to Python and to the model). Notice how run-prompt works with the Ollama tool_calls response object. When the LLM determines that a specific task—such as checking the weather or reading a file—requires external data, it returns a structured request rather than a text response. The script intercepts these requests, looks up the corresponding Hy function by name, and executes it using Hy’s #** keyword argument unpacking (Python’s “double-splat” **). This allows the model to pass complex parameters directly into the Hy functions, such as the location for a weather check or a uri for Markdown conversion, with minimal boilerplate.
Furthermore, the script provides an excellent look at how to manage state and connectivity in an LLM application. The helper function choose prints a numbered menu and keeps asking until it gets a valid number, and the try form around run-prompt handles common runtime issues like invalid user input or connection errors to the Ollama server. This interactive approach not only makes the system easier to debug but also serves as a template for more complex AI agents that might need to switch between different models or handle a diverse array of specialized tools depending on the current task context.
Wrap Up for Running Local LLMs Using Ollama
I spend most of my development time working with smaller LLMs running on Ollama (LM Studio is another good choice for running locally).
There are obvious privacy and security advantages running LLMs locally and very interesting and useful engineering problems can sometimes be solved with smaller models.
Optional Practice Problems
Here are a few optional practice problems to help you build a deeper understanding of local LLM tool use and structured outputs using the Hy language:
Implement a New API Tool: Modify tools.hy to add a new tool function, such as
get-github-user-bio(which queries the public GitHub API for a user’s bio) orget-joke(which fetches a programming joke from a public API likehttps://icanhazdadjoke.com/). Remember to provide a clear docstring explaining the parameters so that Ollama can parse the metadata schema correctly. Update theavailable-functionsmapping and the:toolslist in ollama_tools_examples.hy to register and test your new tool.Complete the Tool-Use Loop (Multi-Turn Chat): In ollama_tools_examples.hy, when the model requests a tool call, the script executes the Hy function locally and prints its output to the console. However, it does not send the tool’s response back to the LLM to generate a final answer. Modify the script to append the tool’s output as a new message with the role
"tool"(or"user", depending on the model’s specification) and send the entire conversation history back to the model usingclient.chatto receive the final synthesized response.Enforce Structured JSON Outputs: Modify the completion function in completion_local.hy to request structured JSON output from Ollama. You can pass
:format "json"toollama.chatand instruct the model in your prompt to return the age differences as a JSON array of objects (e.g.,[{"person1": "Sally", "person2": "Bill", "difference": 45}]). Use Python’sjsonlibrary to parse the returned content and print it as a Hy dictionary.