Datastores
I use flat files and the PostgreSQL relational database for most data storage and processing needs in my consulting business over the last twenty years. For work on large data projects at Compass Labs and Google I used Hadoop and Big Table. I will not cover big data datastores here, rather I will concentrate on what I think of as “laptop development” requirements: a modest amount of data and optimizing speed of development and ease of infrastructure setup. We will cover three datastores:
- Sqlite single-file-based relational database
- PostgreSQL relational database
- RDF library rdflib that is useful for semantic web and linked data applications
For graph data we will stick with RDF because it is a fairly widely used standard. Google, Microsoft, Yahoo and Yandex support schema.org for defining schemas for structured data on the web. In the next chapter we will go into more details on RDF, here we look at the “plumbing” for using the rdflib library to manipulate and query RDF data and how to export RDF data in several formats. Then in a later chapter, we will develop tools to automatically generate RDF data from raw text as a tool for developing customized Knowledge Graphs.
In one of my previous books Loving Common Lisp, or the Savvy Programmer’s Secret Weapon I also covered the general purpose graph database Neo4j which I like to use for some use cases, but for the purposes of this book we stick with RDF.
Sqlite
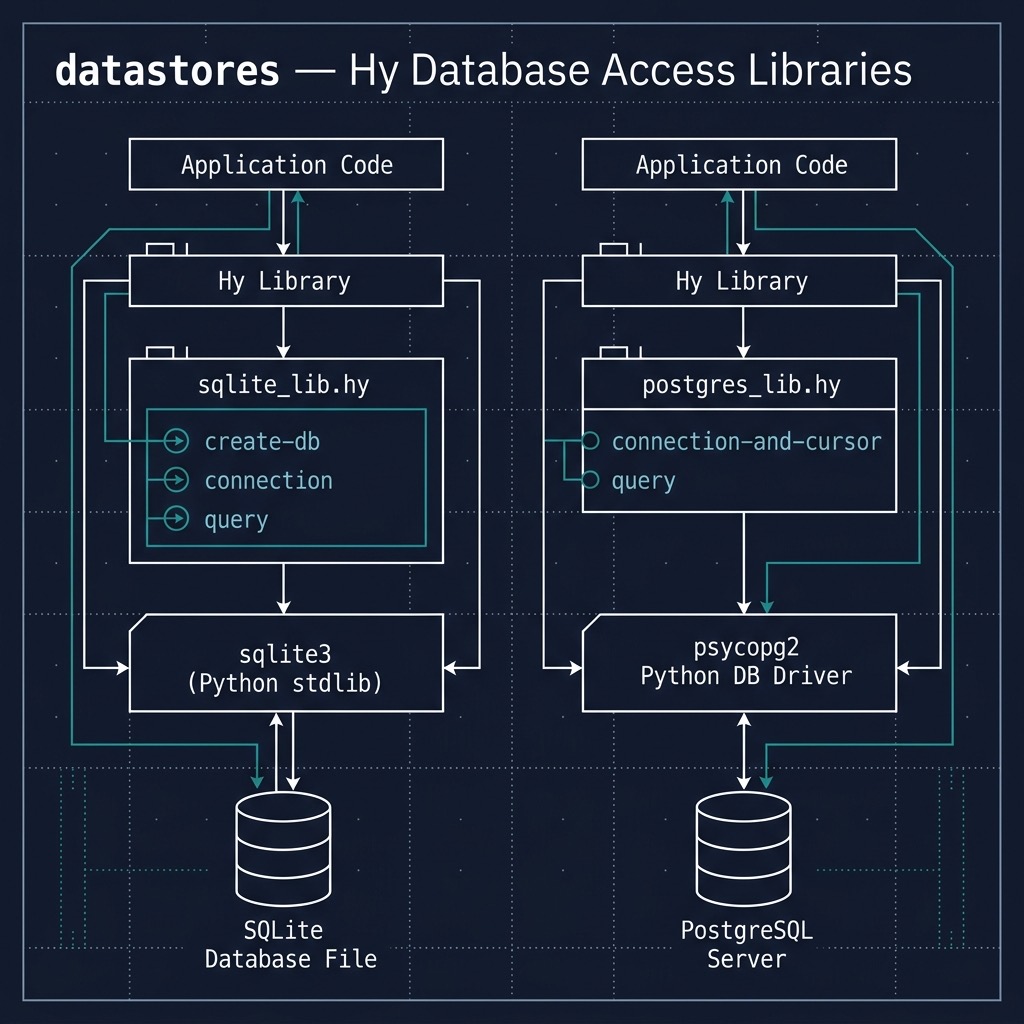
We will cover two relational databases: Sqlite and PostgreSQL. Sqlite is an embedded database. There are Sqlite libraries for many programming languages and here we use the Python library.
The following examples are simple but sufficient to show you how to open a single file Sqlite database, add data, modify data, query data, and delete data. I assume that you have some familiarity with relational databases, especially concepts like data columns and rows, and SQL queries.
Let’s start with putting common code for using Sqlite into a reusable library in the file sqlite_lib.hy:
 1 ;; SQLite utility functions for Hy
 2
 3 (import sqlite3)
 4
 5 (defn connection [db-file-path]
 6   "Open and return a connection to the SQLite database in DB-FILE-PATH,
 7   creating the file if needed. Use \":memory:\" for an in-memory database."
 8   (sqlite3.connect db-file-path))
 9
10 (defn query [conn sql [params #()]]
11   "Execute SQL with optional PARAMS bound to ? placeholders and return all
12   result rows (an empty list for statements like INSERT). The change is
13   committed if the statement succeeds and rolled back if it raises."
14   (with [conn]   ; a sqlite3 connection used with `with` manages a transaction
15     (.fetchall (.execute conn sql params))))
The function connection (lines 5-8) opens a connection to a database defined by a file path to the single file used for a Sqlite database, creating the file if it does not already exist. The special path “:memory:” creates a temporary in-memory database instead. This connection can be reused for many queries. The function query (lines 10-15) executes any SQL statement, optionally binding values from params to ? placeholders in the SQL, and returns all result rows.
Notice the with form on line 14. A Python sqlite3 connection used as a context manager wraps the statement in a transaction: if the statement succeeds the change is committed, and if it raises an exception the change is rolled back. Without the commit, inserts and updates to a database file would be silently lost when the program exits.
The following listing of file sqlite_example.hy shows how to use this simple library:
 1 #!/usr/bin/env hy
 2
 3 ;; Demonstrates common SQLite operations using the sqlite-lib wrapper.
 4 ;; The database is kept in memory (":memory:") so no file is created on disk.
 5
 6 (import sqlite-lib [connection query])
 7
 8 (defn main []
 9   ;; Replace ":memory:" with a file path like "people.db" to keep the data.
10   (setv conn (connection ":memory:"))
11   (query conn "CREATE TABLE people (name TEXT, email TEXT)")
12
13   ;; INSERT returns an empty list because there are no rows to fetch back.
14   ;; The ? placeholders are filled in from the list of values, which
15   ;; prevents SQL injection.
16   (for [[name email] [["Mark" "mark@markwatson.com"]
17                       ["Kiddo" "kiddo@markwatson.com"]
18                       ["Alice" "alice@example.com"]]]
19     (print "Insert" name ":"
20            (query conn "INSERT INTO people VALUES (?, ?)" [name email])))
21
22   (print "All people:" (query conn "SELECT * FROM people"))
23   (print "Lookup by email:"
24          (query conn "SELECT name FROM people WHERE email = ?" ["mark@markwatson.com"]))
25
26   (query conn "UPDATE people SET name = ? WHERE email = ?"
27          ["Mark Watson" "mark@markwatson.com"])
28   (query conn "DELETE FROM people WHERE name = ?" ["Kiddo"])
29   (print "After update and delete:"
30          (query conn "SELECT * FROM people ORDER BY name"))
31
32   ;; COUNT(*) returns a list with a single one-element tuple
33   (setv [[n]] (query conn "SELECT COUNT(*) FROM people"))
34   (print "Total rows remaining:" n)
35   (conn.close))
36
37 (when (= __name__ "__main__")
38   (main))
We opened an in-memory database on line 10 but we could have also created a persistent database on disk using, for example, “people.db” instead of “:memory:”. In line 11 we create a database table with just two columns, each column holding string values.
In lines 16-20 we insert three rows. Always use placeholders like ? for values instead of building SQL strings by concatenation: the database driver then treats the values strictly as data, which prevents SQL injection attacks. In line 22 we use a wild card query using the asterisk character to return all column values for each matched row in the database.
Running the example program produces the following output:
1 $ uv run hy sqlite_example.hy
2 Insert Mark : []
3 Insert Kiddo : []
4 Insert Alice : []
5 All people: [('Mark', 'mark@markwatson.com'), ('Kiddo', 'kiddo@markwatson.com'), ('Alice', 'alice@example.com')]
6 Lookup by email: [('Mark',)]
7 After update and delete: [('Alice', 'alice@example.com'), ('Mark Watson', 'mark@markwatson.com')]
8 Total rows remaining: 2
The INSERT statements return empty lists because statements that create tables or insert, update, or delete rows do not return rows.
In the next section we will see how PostgreSQL treats JSON data as a native data type. For Sqlite, you can store JSON data as a “dumped” string value and decode it when you read it back:
1 (import json)
2
3 (setv profile {"languages" ["Hy" "Common Lisp"]})
4 (query conn "CREATE TABLE profiles (name TEXT, data TEXT)")
5 (query conn "INSERT INTO profiles VALUES (?, ?)" ["Mark" (json.dumps profile)])
6 (setv [[data]] (query conn "SELECT data FROM profiles WHERE name = ?" ["Mark"]))
7 (json.loads data)  ;; => {'languages': ['Hy', 'Common Lisp']}
(Recent versions of Sqlite also include JSON functions such as json_extract that can look inside JSON strings in queries, but PostgreSQL’s support is more complete.)
PostgreSQL
We just saw use cases for the Sqlite embedded database. Now we look at my favorite general purpose database, PostgreSQL. The PostgreSQL database server is available as a managed service on most cloud providers and it is easy to also run a PostgreSQL server on your laptop or on a VPS or server.
We will use version 3 of the psycopg PostgreSQL adapter. It is already a dependency in the uv project in source_code_for_examples/datastores (as psycopg[binary], which includes a compiled copy of the PostgreSQL client library so nothing else needs to be installed). If you see older code that imports psycopg2, the APIs are very similar.
The following material is self-contained but before using PostgreSQL and psycopg in your own applications I recommend that you reference the psycopg documentation.
Notes for Using PostgreSQL and Setting Up an Example Database “hybook” on macOS and Linux
The following two sections may help you get PostgreSQL set up on macOS and Linux.
macOS
On macOS I install PostgreSQL with Homebrew (or use the Postgres.app application) and start the server as a background service:
1 brew install postgresql@17
2 brew services start postgresql@17
Homebrew sets up a database superuser with the same name as your macOS login, so you can create the database hybook directly:
1 $ createdb hybook
2 $ psql -d hybook -c "SELECT version();"
Linux
For Ubuntu Linux install PostgreSQL with apt, which also starts the server. Then create a database user with your login name and the hybook database owned by that user:
1 sudo apt install postgresql
2 sudo -u postgres createuser --createdb $USER
3 createdb hybook
The examples below create and drop their own tables, so this empty database is all you need.
Using Hy with PostgreSQL
When using Hy (or any other Lisp language and also for Haskell), I usually start both coding and experimenting with new libraries and APIs in a REPL. Let’s do that here to see from a high level how we can use psycopg with the database hybook that we created in the last section:
 1 $ uv run hy
 2 => (import psycopg)
 3 => (import psycopg.types.json [Jsonb])
 4 => (setv conn (psycopg.connect :dbname "hybook"))
 5 => (conn.execute "CREATE TABLE news (uri TEXT, title TEXT, nlpdata JSONB)")
 6 => (conn.execute "INSERT INTO news VALUES (%s, %s, %s)"
 7 ...   ["http://knowledgebooks.com/schema" "test schema" (Jsonb {"type" "news"})])
 8 => (conn.commit)
 9 => (.fetchall (conn.execute "SELECT * FROM news"))
10 [('http://knowledgebooks.com/schema', 'test schema', {'type': 'news'})]
11 => (.fetchall (conn.execute "SELECT nlpdata->>'type' FROM news"))
12 [('news',)]
13 => (conn.execute "DROP TABLE news")
14 => (conn.commit)
15 =>
In line 5 the column nlpdata has the type JSONB, PostgreSQL’s native binary JSON data type. In line 7 the Jsonb wrapper tells psycopg to send a Hy dictionary as a JSON value, and line 10 shows that JSON values come back as Hy dictionaries. Line 11 uses the ->> operator to extract a value from inside the JSON data as part of a SQL query. Notice that we need to call commit to make changes permanent: by default psycopg starts a transaction with the first statement.
As with most of the material in this book, I hope that you have a Hy REPL open and are experimenting with the APIs and code in the book’s interactive REPL examples.
The file postgres_lib.hy wraps commonly used functionality for accessing a database, adding, modifying, and querying data in a short reusable library. I gave it the same two functions as sqlite_lib.hy so code can easily switch between the two databases:
 1 ;; PostgreSQL utility functions for Hy, using the psycopg (version 3) driver.
 2 ;; The interface matches sqlite_lib.hy, so code can switch between them.
 3
 4 (import psycopg)
 5
 6 (defn connection [dbname [user None] #** kwargs]
 7   "Open and return a connection to the PostgreSQL database DBNAME. USER
 8   defaults to your login name; extra keyword arguments such as :host,
 9   :port, and :password are passed to psycopg.connect."
10   (psycopg.connect :dbname dbname :user user #** kwargs))
11
12 (defn query [conn sql [params None]]
13   "Execute SQL with optional PARAMS bound to %s placeholders and return all
14   result rows (an empty list for statements like INSERT). The change is
15   committed if the statement succeeds and rolled back if it raises."
16   (with [(.transaction conn)]
17     (setv cursor (.execute conn sql params))
18     ;; cursor.description is None when a statement returns no rows
19     (if cursor.description (.fetchall cursor) [])))
The function connection (lines 6-10) passes any extra keyword arguments such as :host or :password through to psycopg.connect. If you don’t give a user name, psycopg uses your login name. The function query in lines 12-19 executes any SQL command so in addition to querying a database, it can also be used with appropriate SQL commands to delete rows, update rows, and create and destroy tables. The with form on line 16 runs the statement in a transaction that is committed when the block finishes normally and rolled back if an exception is raised. Statements like INSERT have no result rows, which psycopg indicates by setting the cursor’s description to None, so in that case we return an empty list (line 19).
The following file postgres_example.hy contains examples for using the library we just defined. It reads the database name from the standard PostgreSQL environment variable PGDATABASE, using hybook if it is not set:
 1 #!/usr/bin/env hy
 2
 3 ;; Demonstrates postgres-lib, including PostgreSQL's native JSONB data type.
 4 ;; Set PGDATABASE (default "hybook") and, if needed, PGUSER and PGHOST.
 5
 6 (import os)
 7 (import psycopg.types.json [Jsonb])
 8 (import postgres-lib [connection query])
 9
10 (defn main []
11   (with [conn (connection (os.environ.get "PGDATABASE" "hybook"))]
12     (query conn "CREATE TABLE people (name TEXT, email TEXT, profile JSONB)")
13     (try
14       ;; Jsonb wraps a Hy dictionary so psycopg sends it as a JSONB value
15       (query conn "INSERT INTO people VALUES (%s, %s, %s)"
16              ["Mark" "mark@markwatson.com"
17               (Jsonb {"languages" ["Hy" "Common Lisp" "Python"] "city" "Flagstaff"})])
18       (query conn "INSERT INTO people VALUES (%s, %s, %s)"
19              ["Kiddo" "kiddo@markwatson.com" (Jsonb {"languages" ["Python"]})])
20       (print "All people:" (query conn "SELECT name, email FROM people ORDER BY name"))
21
22       ;; JSONB values come back as Hy dictionaries...
23       (setv [[profile]] (query conn "SELECT profile FROM people WHERE name = %s" ["Mark"]))
24       (print "Mark's city:" (get profile "city"))
25       ;; ...and the database can query inside them: ? tests array membership
26       (print "Hy programmers:"
27              (query conn "SELECT name FROM people WHERE profile->'languages' ? %s" ["Hy"]))
28
29       (query conn "UPDATE people SET name = %s WHERE email = %s"
30              ["Mark Watson" "mark@markwatson.com"])
31       (query conn "DELETE FROM people WHERE name = %s" ["Kiddo"])
32       (print "After update and delete:" (query conn "SELECT name, email FROM people"))
33       (finally
34         (query conn "DROP TABLE people")))))
35
36 (when (= __name__ "__main__")
37   (main))
The try/finally form starting at line 13 makes sure that the people table is dropped even if one of the statements fails, so you can run the example repeatedly. In lines 25-27 we let the database search inside the JSON data: the ? operator is true when a JSON array contains a given string.
Here is the output from this example Hy script:
1 $ uv run hy postgres_example.hy
2 All people: [('Kiddo', 'kiddo@markwatson.com'), ('Mark', 'mark@markwatson.com')]
3 Mark's city: Flagstaff
4 Hy programmers: [('Mark',)]
5 After update and delete: [('Mark Watson', 'mark@markwatson.com')]
I use PostgreSQL more than any other datastore and taking the time to learn how to manage PostgreSQL servers and write application software will save you time and effort when you are prototyping new ideas or developing data oriented product at work. I love using PostgreSQL and personally, I only use Sqlite for very small database tasks or applications.
RDF Data Using the “rdflib” Library
While the last two sections on Sqlite and PostgreSQL provided examples that you are likely to use in your own work, we will now turn to something more esoteric but still useful, the RDF notations for using data schema and RDF triple graph data in semantic web, linked data, and Knowledge Graph applications. I used graph databases working with Google’s Knowledge Graph when I worked there and I have had several consulting projects using linked data. I currently work on the Knowledge Graph team at Olive AI. You will need to understand the material in this section for the two chapters that take a deeper dive into the semantic web and linked data and also develop an example that automatically creates Knowledge Graphs.
In my work I use RDF as a notation for graph data, RDFS (RDF Schema) to define formally data types and relationship types in RDF data, and occasionally OWL (Web Ontology Language) for reasoning about RDF data and inferring new graph triple data from data explicitly defined. Here we will only cover RDF since it is the most practical linked data tool and I refer you to my other semantic web books for deeper coverage of RDF as well as RDFS and OWL.
We will go into some detail on using semantic web and linked data resources in the next chapter. Here we will study the use of library rdflib as a data store, reading RDF data from disk and from web resources, adding RDF statements (which are triples containing a subject, predicate, and object) and for serializing an in-memory graph to a file in one of the standard RDF XML, turtle, or NT formats.
We use the rdflib library, which (since version 6) includes support for the JSON-LD format. The library and Hy are configured for the uv environment in the directory hy-lisp-python-book/source_code_for_examples/rdf.
The following REPL session shows importing the rdflib library, fetching a small RDF file (in XML format) from one of the W3C’s RDF test suites, printing out the triples in the graph, and showing how the graph can be queried. The following REPL session is split up into several listings so I can explain how the rdflib is being used. In the first REPL listing I load the RDF file and print its triples. NT format can have either subject/predicate/object all on one line separated by spaces and terminated by a period or as shown below, the subject is on one line with predicate and objects printed indented on two additional lines. In both cases a period character “.” is used to terminate each RDF NT statement. The statements are displayed in arbitrary order. The subject here is a blank node, a resource without a URI, which rdflib gives a random identifier like N0606a4fc…; you will see different identifiers each time you load the file.
 1 $ cd hy-lisp-python-book/source_code_for_examples/rdf
 2 $ uv run hy
 3 Hy 1.3.1 (Eyes in the Sky) using CPython(main) 3.14.7 on Darwin
 4 => (import rdflib [Graph])
 5 => (setv graph (Graph))
 6 => (graph.parse "https://www.w3.org/2000/10/rdf-tests/RDF-Model-Syntax_1.0/ms_4.1_1.rdf")
 7 <Graph identifier=N17cc149204994200a3388a2bf876090b (<class 'rdflib.graph.Graph'>)>
 8 => (for [[subject predicate object] graph]
 9 ...   (print subject "\n  " predicate "\n  " object " ."))
10 N0606a4fc1dce4d79843ead3a26db6c76
11    http://www.w3.org/1999/02/22-rdf-syntax-ns#type
12    http://www.w3.org/1999/02/22-rdf-syntax-ns#Statement  .
13 N0606a4fc1dce4d79843ead3a26db6c76
14    http://description.org/schema/attributedTo
15    Ralph Swick  .
16 N0606a4fc1dce4d79843ead3a26db6c76
17    http://www.w3.org/1999/02/22-rdf-syntax-ns#object
18    Ora Lassila  .
19 N0606a4fc1dce4d79843ead3a26db6c76
20    http://www.w3.org/1999/02/22-rdf-syntax-ns#subject
21    http://www.w3.org/Home/Lassila  .
22 N0606a4fc1dce4d79843ead3a26db6c76
23    http://www.w3.org/1999/02/22-rdf-syntax-ns#predicate
24    http://description.org/schema/Creator  .
25 =>
There are several available formats for serializing RDF data. Here we will serialize using the JSON-LD format (later we will also see examples for serializing in NT and Turtle formats):
 1 => (print (graph.serialize :format "json-ld" :indent 2))
 2 [
 3   {
 4     "@id": "_:N0606a4fc1dce4d79843ead3a26db6c76",
 5     "@type": [
 6       "http://www.w3.org/1999/02/22-rdf-syntax-ns#Statement"
 7     ],
 8     "http://description.org/schema/attributedTo": [
 9       {
10         "@value": "Ralph Swick"
11       }
12     ],
13     "http://www.w3.org/1999/02/22-rdf-syntax-ns#object": [
14       {
15         "@value": "Ora Lassila"
16       }
17     ],
18     "http://www.w3.org/1999/02/22-rdf-syntax-ns#predicate": [
19       {
20         "@id": "http://description.org/schema/Creator"
21       }
22     ],
23     "http://www.w3.org/1999/02/22-rdf-syntax-ns#subject": [
24       {
25         "@id": "http://www.w3.org/Home/Lassila"
26       }
27     ]
28   }
29 ]
JSON-LD is convenient for implementing APIs that are intended for use by developers who are not familiar with RDF technology.
We will cover the SPARQL query language in more detail in the next chapter but for now, notice that SPARQL is similar to SQL queries. SPARQL queries can find triples in a graph matching simple patterns, match complex patterns, and update and delete triples in a graph. The following simple SPARQL query finds all triples with the predicate equal to http://www.w3.org/2000/10/swap/pim/contact#company and prints out the subject and object of any matching triples:
1 => (for [[subject object]
2 ... (graph.query
3 ...  "select ?subject ?object where { ?subject <http://description.org/schema/attributedTo> ?object }")]
4 ... (print subject "attributedTo: " object))
5 N0606a4fc1dce4d79843ead3a26db6c76 attributedTo:  Ralph Swick
We will see more examples of the SPARQL query language in the next chapter. For now, notice that the general form of a select query statement is a list of query variables (names beginning with a question mark) and a where clause in curly brackets that contains matching patterns. This SPARQL query is simple, but like SQL queries, SPARQL queries can get very complex. I only lightly cover SPARQL in this book. You can get PDF copies of my two older semantic web books for free: Practical Semantic Web and Linked Data Applications, Java, Scala, Clojure, and JRuby Edition and Practical Semantic Web and Linked Data Applications, Common Lisp Edition. There are links to relevant git repos and other information on my book web page.
In addition to the Turtle format I also use the simpler NT format that puts URI prefixes inline and unlike Turtle does not use prefix abbreviations. Here we serialize to NT format (I added line breaks to fit the page width):
 1 => (print (graph.serialize :format "nt"))
 2 _:N0606a4fc1dce4d79843ead3a26db6c76
 3   <http://www.w3.org/1999/02/22-rdf-syntax-ns#type>
 4   <http://www.w3.org/1999/02/22-rdf-syntax-ns#Statement> .
 5 _:N0606a4fc1dce4d79843ead3a26db6c76
 6   <http://description.org/schema/attributedTo>
 7   "Ralph Swick" .
 8 _:N0606a4fc1dce4d79843ead3a26db6c76
 9   <http://www.w3.org/1999/02/22-rdf-syntax-ns#object>
10   "Ora Lassila" .
11 _:N0606a4fc1dce4d79843ead3a26db6c76
12   <http://www.w3.org/1999/02/22-rdf-syntax-ns#subject>
13   <http://www.w3.org/Home/Lassila> .
14 _:N0606a4fc1dce4d79843ead3a26db6c76
15   <http://www.w3.org/1999/02/22-rdf-syntax-ns#predicate> <http://description.org/schema/Creator> .
16 =>
Using RDFLIB with in-memory RDF triple storage is very convenient with small or mid-size RDF data sets as long as initializing the data store by reading a local file containing RDF triples is a fast operation. If I need to use large RDF data sets I prefer to not use rdflib and instead use SPARQL to access a free or open source standalone RDF data store like OpenLink Virtuoso or GraphDB™ Free Edition. I also like and recommend the commercial AllegroGraph and Stardog RDF server products.
Wrap-up
We will go into much more detail on practical uses of RDF and SPARQL in the next chapter. I hope that you worked through the REPL examples in this section because if you understand the basics of using the rdflib then you will have an easier time understanding the more abstract material in the next chapter.
Optional Practice Problems
- Persistent SQLite Storage and Custom Columns: The SQLite database in
sqlite_example.hycurrently uses":memory:"as a connection string, meaning all data is lost when the program exits. Modify the script to use a local file (e.g.,"contacts.db") to persist your data. Additionally, modify the database schema to add a newagecolumn to thepeopletable, and update the insertion queries and formatting to print this new field. - Parameterized SQLite Insertions: In
sqlite_example.hy, several of theINSERTstatements are hardcoded as raw SQL strings without parameter bindings. Refactor all insertion queries to use SQLite parameter bindings (using?placeholders and passing parameters in a list toquery) to prevent potential SQL injection and clean up the string construction code. - PostgreSQL JSON Queries: While PostgreSQL supports native JSON/JSONB data types, our simplified
postgres_example.hyscript only uses text columns. Using a local PostgreSQL instance, create a table with a JSONB column (e.g., storing a structure like{"status": "active", "roles": ["admin"]}). Add code to insert sample records containing JSON-like dictionary structures, and query the records using PostgreSQL’s json/jsonb query operators (such as->>or@>).