Web Scraping
I often write software to automatically collect and use data from the web and other sources. As a practical matter, much of the data that many people use for machine learning comes from either the web or from internal data sources. This section provides some guidance and examples for getting text data from the web.
Before we start a technical discussion about web scraping I want to point out that much of the information on the web is copyright and the first thing that you should do is to read the terms of service for web sites to insure that your use of “scraped” or “spidered” data conforms with the wishes of the persons or organizations who own the content and pay to run scraped web sites.
Web Scraping Using the jsoup Library
We will use the MIT licensed Java library jsoup. One reason I selected jsoup for the examples in this chapter out of many fine libraries that provide similar functionality is the particularly nice documentation, especially The jsoup Cookbook which I urge you to bookmark as a general reference. In this chapter I will concentrate on just the most frequent web scraping use cases that I use in my own work: getting all plain text and links from a web site. It should be straightforward for you to take the following example and extend it with whatever else you may need from the jsoup Cookbook.
We need to require the jsoup dependency in the project file:
1 (defproject webscraping "0.1.0-SNAPSHOT"
2   :description "Demonstration of using Java Jsoup library"
3   :url "https://markwatson.com"
4   :license {:name "EPL-2.0 OR GPL-2.0-or-later WITH Classpath-exception-2.0"
5             :url "https://www.eclipse.org/legal/epl-2.0/"}
6   :dependencies [[org.clojure/clojure "1.12.6"]
7                  [org.jsoup/jsoup "1.22.1"]]
8   :main webscraping.core
9   :repl-options {:init-ns webscraping.core})
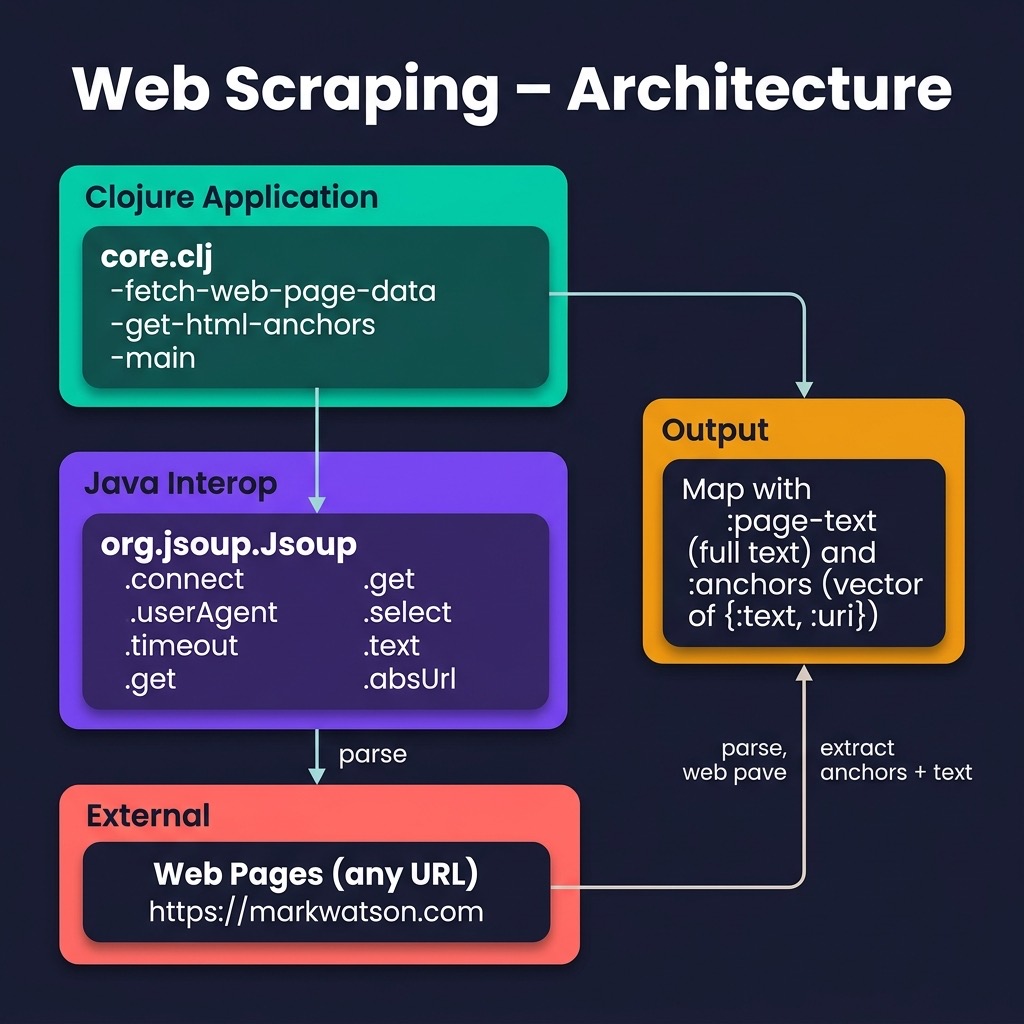
The example code for this chapter uses jsoup to get the complete plain text and also the anchor (<a href=…) data for a web page. In reading the following code let’s start at the end: lines 18-34 where we fetch data from a web site as a jsoup document object. Once we have this document object, we use the Java method text to get plain text. On line 30 we use the utility function get-html-anchors that is defined in lines 6-16. On line 7 we search for all anchor patterns "a[href]". For each anchor, we extract the trimmed link text with (. anchor text) and resolve relative or absolute target URIs using Jsoup’s built-in (. anchor absUrl "href") method.
 1 (ns webscraping.core
 2   (:require [clojure.string :as str]))
 3
 4 (import (org.jsoup Jsoup))
 5
 6 (defn get-html-anchors [jsoup-web-page-contents]
 7   (let [anchors (. jsoup-web-page-contents select "a[href]")]
 8     (->> anchors
 9          (map (fn [anchor]
10                 (try
11                   {:text (str/trim (. anchor text))
12                    :uri (. anchor absUrl "href")}
13                   (catch Exception e
14                     (binding [*out* *err*] (println (str "Error processing anchor: " (.getMessage e) " on page: " (. jsoup-web-page-contents title))))
15                     nil))))
16          (filterv some?))))
17
18 (defn fetch-web-page-data
19   "Get the <a> anchor data and full text from a web URI"
20   [a-uri]
21   (try
22     (let [doc
23           (->
24             (. Jsoup connect a-uri)
25             (.userAgent
26               "Mozilla/5.0 (Macintosh; Intel Mac OS X 10.0; rv:77.0) Gecko/20100101 Firefox/77.0")
27             (.timeout 20000)
28             (.get))
29           all-page-text (. doc text)
30           anchors (get-html-anchors doc)]
31       {:page-text all-page-text :anchors anchors})
32     (catch Exception e
33       (binding [*out* *err*] (println (str "Error fetching page " a-uri ": " (.getMessage e))))
34       {:page-text nil :anchors []})))
On lines 25-26 I am setting the same user agent as my local web browser. In principle I would prefer making up a user agent name that contains my name and why I am spidering data, but in practice some web sites refuse requests from non-standard agents.
Let’s look at the test code for fetching text and links from my personal web site and verifying relative and absolute URI resolution:
 1 (ns webscraping.core-test
 2   (:require [clojure.test :refer :all]
 3             [clojure.pprint :as pp]
 4             [clojure.string :as str]
 5             [webscraping.core :refer :all])
 6   (:import (org.jsoup Jsoup)))
 7
 8 (deftest no-anchors-test
 9   (testing "Page with no anchor tags"
10     (let [html-doc (Jsoup/parse "<html><body><p>No links here.</p></body></html>")
11           anchors (get-html-anchors html-doc)]
12       (is (empty? anchors) "Expected no anchors from HTML with no links"))))
13
14 (deftest relative-and-absolute-uris-test
15   (testing "Anchor URI resolution for relative and absolute paths"
16     (let [base-uri "http://example.com/docs/"
17           html-content "<html><body><a href=\"/page1\">Page 1</a> <a href=\"http://domain.com/page2\">Page 2</a> <a href=\"../page3\">Page 3</a> <a href=\"sub/page4\">Page 4</a><a href=\"page5.html\">Page 5</a></body></html>"
18           html-doc (. Jsoup parse html-content base-uri)
19           anchors (get-html-anchors html-doc)
20           uris (set (map :uri anchors))]
21       (is (contains? uris "http://example.com/page1"))
22       (is (contains? uris "http://domain.com/page2"))
23       (is (contains? uris "http://example.com/page3"))
24       (is (contains? uris "http://example.com/docs/sub/page4"))
25       (is (contains? uris "http://example.com/docs/page5.html")))))
Output might look like (most of the output is not shown):
 1 {:page-text
 2  "Mark Watson: AI Practitioner and Lisp Hacker ...",
 3  :anchors
 4  ({:text "Read my Blog",
 5    :uri "https://mark-watson.blogspot.com"}
 6   {:text "Fun stuff",
 7    :uri "https://markwatson.com#fun"}
 8   {:text "My Books",
 9    :uri "https://markwatson.com#books"}
10   {:text "My Open Source Projects",
11    :uri "https://markwatson.com#opensource"}
12  ...
13   {:text "leanpub",
14    :uri "https://leanpub.com/u/markwatson"}
15   {:text "GitHub",
16    :uri "https://github.com/mark-watson"}
17   {:text "LinkedIn",
18    :uri "https://www.linkedin.com/in/marklwatson/"}
19   {:text "Twitter",
20    :uri "https://twitter.com/mark_l_watson"}
21 ... )}
For training data for machine learning it is useful to just grab all text on a web page and assume that common phrases dealing with web navigation, etc., will be dropped from learned models because they occur in many different training examples for different classifications.
I find the jsoup library to be robust for fetching and parsing HTML data from web pages. As we have seen, it is straightforward to use jsoup in Clojure projects.
Optional Practice Problems
- Hyperlink Classification: Extend the scraper in
source-code/webscrapingto extract allhrefattributes from the target webpage and filter them into external vs. internal links. - Resilience & Retries: Add robust error handling and a retry mechanism (e.g., with exponential backoff) for HTTP requests that fail or timeout.
- Table Parser: Extract tabular data from a target webpage and parse it into a sequence of Clojure maps with column headers as keys.