Document Question Answering Using Gemini APIs and a Local Embeddings Vector Database
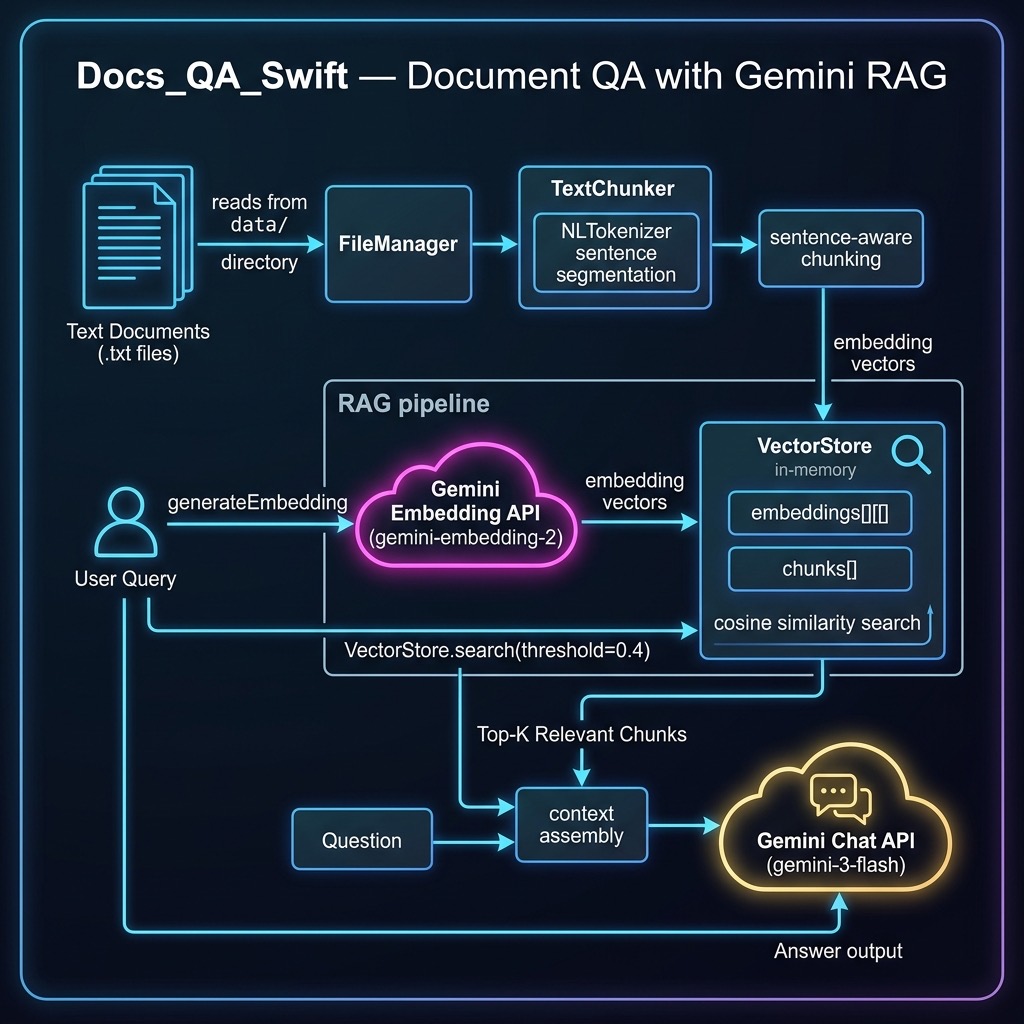
The example in this chapter implements Retrieval-Augmented Generation (RAG) using Google’s Gemini API. We use Gemini Embedding 2 to generate vector embeddings for document chunks and Gemini 3 Flash to answer questions using retrieved context. This approach lets you ground an LLM’s responses in your own local documents.
The source code for this example is in the source-code/Docs_QA_Swift directory. We split the implementation across four Swift source files for clarity:
- GeminiAPI.swift — REST API client for Gemini embeddings and chat
- TextChunker.swift — Sentence-aware text chunking using NLTokenizer
- VectorStore.swift — In-memory vector database with cosine similarity search
- main.swift — Ingests documents and answers questions via RAG
This example requires a GOOGLE_API_KEY environment variable to be set.
Gemini API Client
The GeminiAPI.swift file provides two core capabilities: generating embeddings and performing question answering. Both use the Gemini REST API at generativelanguage.googleapis.com with async/await and Codable for clean, type-safe JSON handling.
Embedding Requests
We define Codable structs for the Gemini embedding API request and response:
 1 private struct EmbedRequest: Codable {
 2     struct Content: Codable {
 3         struct Part: Codable {
 4             let text: String
 5         }
 6         let parts: [Part]
 7     }
 8     let content: Content
 9 }
10
11 private struct EmbedResponse: Codable {
12     struct Embedding: Codable {
13         let values: [Double]
14     }
15     let embedding: Embedding
16 }
The generateEmbedding function sends text to the Gemini embedContent endpoint and returns a normalized vector:
 1 func generateEmbedding(for text: String,
 2                        apiKey: String)
 3                        async -> [Double]? {
 4     let model = "models/gemini-embedding-2"
 5     let urlString =
 6         "\(geminiBase)\(model):embedContent?key=\(apiKey)"
 7     guard let url = URL(string: urlString) else {
 8         return nil
 9     }
10
11     let body = EmbedRequest(
12         content: EmbedRequest.Content(
13             parts: [EmbedRequest.Content.Part(text: text)]
14         )
15     )
16
17     var request = URLRequest(url: url)
18     request.httpMethod = "POST"
19     request.setValue("application/json",
20                      forHTTPHeaderField: "Content-Type")
21     request.httpBody = try? JSONEncoder().encode(body)
22
23     do {
24         let (data, response) =
25             try await URLSession.shared.data(for: request)
26         if let http = response as? HTTPURLResponse,
27            !(200...299).contains(http.statusCode) {
28             let body = String(data: data, encoding: .utf8)
29                        ?? "<no body>"
30             fputs("[Embedding Error] HTTP " +
31                   "\(http.statusCode): \(body)\n", stderr)
32             return nil
33         }
34         let decoded = try JSONDecoder().decode(
35             EmbedResponse.self, from: data)
36         return normalized(decoded.embedding.values)
37     } catch {
38         fputs("[Embedding Error] \(error)\n", stderr)
39         return nil
40     }
41 }
Gemini Embedding 2 returns 3072-dimensional vectors. We L2-normalize them immediately so that dot product equals cosine similarity, simplifying later comparisons.
Chat Completion
For question answering we use the Gemini generateContent endpoint with a system instruction that constrains the model to answer using only the provided context:
 1 private struct GeminiRequest: Codable {
 2     let systemInstruction: SystemInstruction?
 3     let contents: [Content]
 4
 5     struct SystemInstruction: Codable {
 6         let parts: [Part]
 7     }
 8     struct Content: Codable {
 9         let parts: [Part]
10     }
11     struct Part: Codable {
12         let text: String
13     }
14 }
15
16 private struct GeminiResponse: Codable {
17     let candidates: [Candidate]?
18
19     struct Candidate: Codable {
20         let content: Content
21     }
22     struct Content: Codable {
23         let parts: [Part]
24     }
25     struct Part: Codable {
26         let text: String
27     }
28 }
The questionAnswering function sends the retrieved context as a system instruction and the user’s question as the content:
 1 func questionAnswering(context: String, question: String,
 2                        apiKey: String) async -> String? {
 3     let model = "models/gemini-3-flash-preview"
 4     let urlString =
 5         "\(geminiBase)\(model):generateContent?key=\(apiKey)"
 6     guard let url = URL(string: urlString) else {
 7         return nil
 8     }
 9
10     let body = GeminiRequest(
11         systemInstruction: GeminiRequest.SystemInstruction(
12             parts: [GeminiRequest.Part(
13                 text: "Answer the user's question using " +
14                       "only the following context:\n\n" +
15                       "\(context)")]
16         ),
17         contents: [
18             GeminiRequest.Content(
19                 parts: [GeminiRequest.Part(text: question)]
20             )
21         ]
22     )
23
24     var request = URLRequest(url: url)
25     request.httpMethod = "POST"
26     request.setValue("application/json",
27                      forHTTPHeaderField: "Content-Type")
28
29     do {
30         request.httpBody =
31             try JSONEncoder().encode(body)
32     } catch {
33         fputs("[Error] Failed to encode: \(error)\n",
34               stderr)
35         return nil
36     }
37
38     do {
39         let (data, response) =
40             try await URLSession.shared.data(for: request)
41         if let http = response as? HTTPURLResponse,
42            !(200...299).contains(http.statusCode) {
43             let body = String(data: data, encoding: .utf8)
44                        ?? "<no body>"
45             fputs("[Chat Error] HTTP " +
46                   "\(http.statusCode): \(body)\n", stderr)
47             return nil
48         }
49         let decoded = try JSONDecoder().decode(
50             GeminiResponse.self, from: data)
51         return decoded.candidates?.first?
52             .content.parts.first?.text
53     } catch {
54         fputs("[Chat Error] \(error)\n", stderr)
55         return nil
56     }
57 }
Vector Math Utilities
We include three small utility functions for vector operations:
 1 func normalized(_ v: [Double]) -> [Double] {
 2     let mag = sqrt(v.reduce(0.0) { $0 + $1 * $1 })
 3     guard mag > 0 else { return v }
 4     return v.map { $0 / mag }
 5 }
 6
 7 func dotProduct(_ a: [Double], _ b: [Double]) -> Double {
 8     guard a.count == b.count else {
 9         fputs("WARNING: vector length mismatch: " +
10               "\(a.count) != \(b.count)\n", stderr)
11         return 0.0
12     }
13     return zip(a, b).reduce(0.0) { $0 + $1.0 * $1.1 }
14 }
15
16 func cosineSimilarity(_ a: [Double],
17                       _ b: [Double]) -> Double {
18     guard !a.isEmpty, a.count == b.count else { return 0.0 }
19     return dotProduct(a, b)
20 }
Since we normalize all vectors when they are generated, cosine similarity reduces to a simple dot product.
Text Chunking
The TextChunker.swift file handles splitting documents into chunks suitable for embedding. We use Apple’s NLTokenizer for sentence segmentation and then group sentences into chunks that don’t exceed a maximum character count:
 1 func segmentTextIntoSentences(text: String) -> [String] {
 2     let tokenizer = NLTokenizer(unit: .sentence)
 3     tokenizer.string = text
 4     return tokenizer.tokens(
 5         for: text.startIndex..<text.endIndex
 6     ).map { range in
 7         String(text[range])
 8     }
 9 }
10
11 func segmentTextIntoChunks(text: String,
12                            maxChunkSize: Int) -> [String] {
13     let sentences = segmentTextIntoSentences(text: text)
14     var chunks: [String] = []
15     var currentChunk = ""
16     var currentSize = 0
17
18     for sentence in sentences {
19         if currentSize + sentence.count < maxChunkSize {
20             currentChunk += sentence
21             currentSize += sentence.count
22         } else {
23             if !currentChunk.isEmpty {
24                 chunks.append(currentChunk)
25             }
26             currentChunk = sentence
27             currentSize = sentence.count
28         }
29     }
30     if !currentChunk.isEmpty {
31         chunks.append(currentChunk)
32     }
33     return chunks
34 }
This approach preserves sentence boundaries so that each chunk contains complete sentences — important for both embedding quality and for providing readable context to the LLM.
In-Memory Vector Store
The VectorStore.swift file provides a simple in-memory vector database:
 1 struct VectorStore {
 2     private(set) var embeddings: [[Double]] = []
 3     private(set) var chunks: [String] = []
 4
 5     mutating func add(chunk: String,
 6                       embedding: [Double]) {
 7         chunks.append(chunk)
 8         embeddings.append(embedding)
 9     }
10
11     var count: Int { chunks.count }
12
13     func search(queryEmbedding: [Double],
14                 threshold: Double = 0.4,
15                 maxResults: Int = 5)
16                 -> [(chunk: String, score: Double)] {
17         var results: [(chunk: String, score: Double)] = []
18         for i in 0..<embeddings.count {
19             let score = cosineSimilarity(
20                 queryEmbedding, embeddings[i])
21             if score > threshold {
22                 results.append((chunks[i], score))
23             }
24         }
25         return results
26             .sorted { $0.score > $1.score }
27             .prefix(maxResults)
28             .map { $0 }
29     }
30 }
The search method computes cosine similarity between the query embedding and every stored chunk, then returns the top matches above a threshold. For a production system you would use a dedicated vector database, but this simple approach works well for small document collections.
The ingestDocuments function reads all .txt files from a directory, chunks them, generates embeddings, and populates the vector store:
 1 func ingestDocuments(from directoryURL: URL,
 2                      apiKey: String,
 3                      chunkSize: Int = 200)
 4                      async -> VectorStore {
 5     var store = VectorStore()
 6     let fileManager = FileManager.default
 7
 8     do {
 9         let contents = try fileManager.contentsOfDirectory(
10             at: directoryURL,
11             includingPropertiesForKeys: nil)
12         let txtFiles = contents.filter {
13             $0.pathExtension == "txt"
14         }
15
16         for file in txtFiles {
17             let text = try String(contentsOf: file,
18                                   encoding: .utf8)
19             let chunks = segmentTextIntoChunks(
20                 text: text.plainText(),
21                 maxChunkSize: chunkSize)
22
23             for chunk in chunks {
24                 if let embedding =
25                     await generateEmbedding(
26                         for: chunk, apiKey: apiKey) {
27                     store.add(chunk: chunk,
28                               embedding: embedding)
29                 }
30             }
31             print("  Indexed \(file.lastPathComponent)" +
32                   " (\(chunks.count) chunks)")
33         }
34     } catch {
35         fputs("[Error] Reading documents: " +
36               "\(error)\n", stderr)
37     }
38
39     return store
40 }
Running the Example
The main.swift file exercises the full RAG pipeline. First it demonstrates embedding similarity, then it indexes the sample documents, and finally it answers three questions. Here is the output:
 1 $ swift run
 2 === Document QA with Gemini ===
 3
 4 Embedding model: gemini-embedding-2
 5 Chat model:      gemini-3-flash-preview
 6
 7 --- Embedding Similarity Demo ---
 8
 9   Embedded: "John bought a new car" (3072 dimensions)
10   Embedded: "Sally drove to the store" (3072 dimensions)
11   Embedded: "The dog saw a cat" (3072 dimensions)
12
13   Similarity("car" vs "drove"): 0.7162
14   Similarity("car" vs "dog/cat"): 0.4965
15   → Related sentences score higher
16
17 --- Indexing Documents ---
18
19   Indexed chemistry.txt (17 chunks)
20   Indexed sports.txt (3 chunks)
21   Indexed health.txt (25 chunks)
22   Indexed economics.txt (15 chunks)
23
24   Total chunks indexed: 60
25
26 --- Question Answering ---
27
28 Q: What is the history of chemistry?
29
30 A: Based on the provided text, the history of chemistry
31 is defined by its evolving definitions and focus:
32
33 *   **1730:** Georg Ernst Stahl defined chemistry as the
34     art of resolving mixed, compound, or aggregate bodies
35     into their principles and composing bodies from those
36     principles.
37 *   **1837:** Jean-Baptiste Dumas characterized chemistry
38     as the science concerned with the laws and effects of
39     molecular forces.
40 *   **1947:** Linus Pauling accepted a definition of
41     chemistry as the science of substances: their
42     structure, properties, and the reactions that change
43     them into other substances.
44 *   **1998:** Professor Raymond Chang broadened the
45     definition to the study of matter and the changes it
46     undergoes.
47
48 ------------------------------------------------------------
49
50 Q: What is the definition of sports?
51
52 A: Based on the provided text, the definition of sport
53 includes the following:
54
55 *   Activities based in physical athleticism or physical
56     dexterity.
57 *   Derived from the Old French *desport* meaning
58     "leisure."
59 *   The oldest English definition (circa 1300) is
60     "anything humans find amusing or entertaining."
61 *   Usually governed by rules to ensure fair competition
62     and consistent adjudication of the winner.
63
64 ------------------------------------------------------------
65
66 Q: What is microeconomics?
67
68 A: Microeconomics examines the behavior of basic elements
69 in the economy, including individual agents — such as
70 households and firms or buyers and sellers — and markets,
71 as well as their interactions.
72
73 ------------------------------------------------------------
The embedding similarity demo shows that semantically related sentences (“bought a car” and “drove to the store”) score higher (0.72) than unrelated ones (“bought a car” and “the dog saw a cat” at 0.50). This cosine similarity metric is what powers the retrieval step: when you ask a question, we embed it and find the most similar document chunks.
The question answering results show that Gemini 3 Flash provides well-structured, factual answers grounded in the retrieved context. The system instruction constrains the model to answer using only the provided document chunks, reducing hallucination.
Chapter Wrap Up
In this chapter we built a complete RAG (Retrieval-Augmented Generation) pipeline in Swift:
- Document ingestion — Read text files, split them into sentence-aware chunks
- Embedding generation — Convert each chunk to a 3072-dimensional vector using Gemini Embedding 2
- Semantic search — Find the most relevant chunks for a query using cosine similarity
- Grounded generation — Feed the retrieved context to Gemini 3 Flash to generate accurate answers
This pattern is the foundation of many production AI applications. The key insight is that by grounding the LLM in your own documents, you get accurate, domain-specific answers rather than relying on the model’s training data alone.
For production use, you would want to replace the in-memory vector store with a persistent vector database like Qdrant, Pinecone, or pgvector, and add features like metadata filtering, hybrid search, and chunk overlap. But the core pattern — embed, retrieve, generate — remains the same.