Chapter 3: The Infinite Loop
We have a problem.
Imagine running the script from Chapter 2 twice. Say “My name is Alice.” Claude says hello. Run it again and ask “What is my name?” Claude says “I don’t know.”
This is because LLMs are stateless. They have total amnesia. Every request is the first time you have ever met.
To build an agent, we need to fix this by creating artificial memory.
The Illusion of Memory
“Memory” in an LLM isn’t a hard drive. It’s a log file.
When you chat with ChatGPT, it doesn’t “remember” what you said 5 minutes ago. Behind the scenes, the code sends the entire conversation history back to the model with every new message.
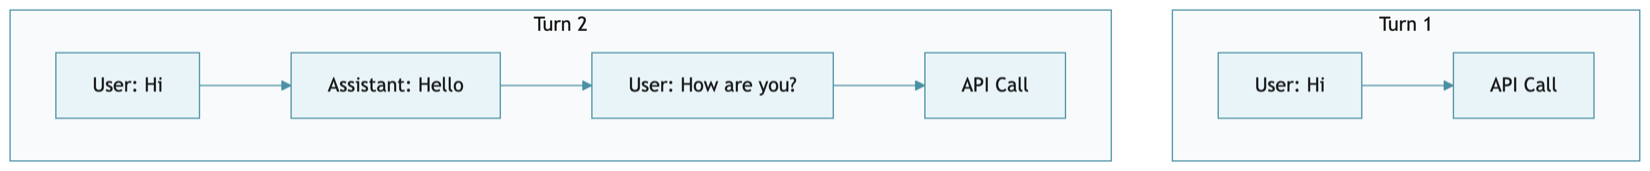
The model sees the full transcript every time. That’s the trick.
Let’s implement this context loop manually. But first, we need to make our code testable.
The Testing Problem
Calling a live LLM on every unit-test run makes the suite slow and unpredictable. Keep those calls for separate integration tests and model evaluations.
API calls are slow (2-10 seconds each), expensive (real money per call), and non-deterministic (you might get a different response every time). Imagine running a test suite that costs $5 and takes 20 minutes. You’d never run it.
The solution is dependency injection. Instead of hardcoding the API call inside our agent, we pass in a “brain” object. In production, the brain is Claude. In tests, the brain is a fake that returns predictable responses.
We’ll establish this pattern now, before writing any more production code.
Response Types
Before we build the brain, we need to define what it returns. Claude’s API sends back complex JSON with multiple content blocks. We need simple Python objects to work with.
The Context: Claude can return text, tool calls, or both in a single response. We need plain data objects to represent these possibilities. (We skip @dataclass deliberately—these classes are simple enough that the decorator would save a few lines while hiding what __init__ actually does.)
The Code:
17 class ToolCall:
18     """A tool invocation request from the brain."""
19
20     def __init__(self, id, name, args):
21         self.id = id
22         self.name = name
23         self.args = args  # dict
ToolCall represents the brain asking us to execute a tool. The id is a unique identifier for tracking (Claude needs it when we report results back). The name is which tool to run. The args is a dictionary of parameters.
We won’t use ToolCall yet—the brain can’t call tools—but we define it now because it’s part of the Thought response type. When we add tools, Claude will return these when it wants to read a file or execute a command.
26 class Thought:
27     """Standardized response from any Brain."""
28
29     def __init__(self, text=None, tool_calls=None, thinking=None):
30         self.text = text  # str or None
31         self.tool_calls = tool_calls or []  # list of ToolCall
32         self.thinking = thinking  # str or None
A Thought is what the brain returns after thinking. It might have text, tool calls, both, or neither. The thinking field captures the model’s reasoning summary—we’ll see where that comes from when we build the Claude class below. This abstraction will let us swap Claude for DeepSeek later without changing any other code.
The FakeBrain Pattern
Now we can build a fake brain for testing.
The Context: We need a brain that returns predictable responses, tracks how many times it was called, and records what conversation it received.
The Code:
class FakeBrain:
    """Fake brain for testing - returns predictable responses."""

    def __init__(self, responses=None):
        self.responses = responses or [Thought(text="Fake response")]
        self.call_count = 0
        self.last_conversation = None

    def think(self, conversation):
        self.last_conversation = list(conversation)  # Store a copy
        if self.call_count < len(self.responses):
            response = self.responses[self.call_count]
            self.call_count += 1
            return response
        return Thought(text="No more responses")
This goes in test_nanocode.py, not the production code. Update that file’s imports to include the response types:
1 import pytest
2 from nanocode import Agent, AgentStop, Thought, ToolCall
Notice that FakeBrain has the same interface as our real brain will—a think() method that takes a conversation and returns a Thought.
Keep the Chapter 1 tests. The updated Agent will require a brain, so change their constructors to Agent(brain=FakeBrain()). For the string-response test, give the fake a response containing hello so both existing assertions still apply:
1 def test_handle_input_returns_string():
2     agent = Agent(brain=FakeBrain(responses=[Thought(text="hello")]))
3     result = agent.handle_input("hello")
4     assert isinstance(result, str)
5     assert "hello" in result
 |
Aside: This pattern—replacing a real dependency with a predictable fake for testing—is called test doubling. Martin Fowler’s article “Mocks Aren’t Stubs”1 explains the variations (fakes, stubs, mocks, spies). For LLM testing, a simple fake with canned responses is usually all you need. |
Defining Success
Before writing the production code, let’s define what success looks like. These tests will guide our implementation.
Test 1: The brain returns a response
1 def test_handle_input_returns_brain_response():
2     """Verify handle_input returns the brain's response text."""
3     brain = FakeBrain(responses=[Thought(text="Hello from brain!")])
4     agent = Agent(brain=brain)
5     result = agent.handle_input("hi")
6     assert result == "Hello from brain!"
Notice we pass brain=brain to the Agent. This is dependency injection in action.
Test 2: Conversation accumulates
 1 def test_conversation_accumulates():
 2     """Verify conversation list grows with each interaction."""
 3     brain = FakeBrain(responses=[
 4         Thought(text="Response 1"),
 5         Thought(text="Response 2")
 6     ])
 7     agent = Agent(brain=brain)
 8
 9     agent.handle_input("First message")
10     assert len(agent.conversation) == 2  # user + assistant
11
12     agent.handle_input("Second message")
13     assert len(agent.conversation) == 4  # 2 users + 2 assistants
After each exchange, the conversation should have both the user message and the assistant response.
Test 3: Correct message structure
 1 def test_conversation_contains_correct_roles():
 2     """Verify conversation has correct role alternation."""
 3     brain = FakeBrain(responses=[Thought(text="AI response")])
 4     agent = Agent(brain=brain)
 5
 6     agent.handle_input("User message")
 7
 8     assert agent.conversation[0]["role"] == "user"
 9     assert agent.conversation[0]["content"] == "User message"
10     assert agent.conversation[1]["role"] == "assistant"
11     assert agent.conversation[1]["content"] == "AI response"
The messages must have the exact format Claude expects: {"role": "user", "content": "..."}.
Test 4: Brain receives the conversation
 1 def test_brain_receives_conversation():
 2     """Verify brain.think is called with the conversation list."""
 3     brain = FakeBrain()
 4     agent = Agent(brain=brain)
 5
 6     agent.handle_input("Test message")
 7
 8     assert brain.last_conversation is not None
 9     assert len(brain.last_conversation) == 1
10     assert brain.last_conversation[0]["content"] == "Test message"
The brain must receive the full conversation, not just the current message.
Run these tests now—they should all fail:
1 pytest test_nanocode.py -v
1 FAILED test_nanocode.py::test_handle_input_returns_brain_response
2 FAILED test_nanocode.py::test_conversation_accumulates
3 ...
Good. Now let’s make them pass.
The Claude Class
Now the real brain. Add these imports and the environment loading call at the top of nanocode.py:
1 import os
2 import requests
3 from dotenv import load_dotenv
4
5 load_dotenv()
The Context: We need a class that wraps the Claude API. It should handle authentication, send conversation history, and parse the response into a Thought. We also enable adaptive thinking: Claude decides when to reason and how much work a request needs. Think of it as a notepad used before speaking; the visible summary is a report of that work, not a complete transcript. Reasoning consumes output tokens and can help with tasks such as choosing tools.
The Code:
37 class Claude:
38     """Claude API - the brain of our agent."""
39
40     def __init__(self):
41         self.api_key = os.getenv("ANTHROPIC_API_KEY")
42         if not self.api_key:
43             raise ValueError("ANTHROPIC_API_KEY not found in .env")
44         self.model = "claude-sonnet-5-5"
45         self.url = "https://api.anthropic.com/v1/messages"
46
47     def think(self, conversation):
48         headers = {
49             "x-api-key": self.api_key,
50             "anthropic-version": "2023-06-01",
51             "content-type": "application/json"
52         }
53         payload = {
54             "model": self.model,
55             "max_tokens": 16000,
56             "thinking": {"type": "adaptive", "display": "summarized"},
57             "output_config": {"effort": "medium"},
58             "messages": conversation
59         }
60
61         response = requests.post(self.url, headers=headers, json=payload, timeout=120)
62         response.raise_for_status()
63         return self._parse_response(response.json()["content"])
The Walkthrough:
- Lines 41-43: Load the API key and fail fast if it’s missing.
- Lines 44-45: Store config. We’ll make the model configurable later.
- Line 47: The
think()method is the brain’s interface—same asFakeBrain. - Lines 55-57:
adaptivelets Claude decide when to think.display: summarizedrequests a visible reasoning summary; Sonnet 5.5 otherwise omits it by default. Medium effort controls reasoning depth, not a fixed token allowance. The 16,000-token output cap covers reasoning and response text together; thinking is billed as output.2 - Line 58: The payload includes
"messages": conversation—the full history, not just the current message. This is the context loop. - Line 63: Parse Claude’s complex response format into our simple
Thought.
Now the response parser:
65     def _parse_response(self, content):
66         """Convert Claude's response format to Thought."""
67         text_parts = []
68         tool_calls = []
69         thinking = None
70
71         for block in content:
72             if block["type"] == "thinking":
73                 thinking = block["thinking"]
74             elif block["type"] == "text":
75                 text_parts.append(block["text"])
76             elif block["type"] == "tool_use":
77                 tool_calls.append(ToolCall(
78                     id=block["id"],
79                     name=block["name"],
80                     args=block["input"]
81                 ))
82
83         return Thought(
84             text="\n".join(text_parts) if text_parts else None,
85             tool_calls=tool_calls,
86             thinking=thinking
87         )
Claude’s API returns a list of “content blocks.” Each block has a type—"thinking", "text", or "tool_use". A thinking block may contain a reasoning summary—we store it on the Thought for the caller to display. It can also be empty or absent, so the display must not assume visible reasoning exists. Text blocks become the response, and tool_use blocks become ToolCall objects. The parser doesn’t print anything; it just converts the raw JSON into a clean Thought.
The Agent Class (Updated)
Now we update the Agent from Chapter 1 to accept a brain and maintain conversation history.
The Code:
 92 class Agent:
 93     """A coding agent with conversation memory."""
 94
 95     def __init__(self, brain):
 96         self.brain = brain
 97         self.conversation = []
 98
 99     def handle_input(self, user_input):
100         """Handle user input. Returns output string, raises AgentStop to quit."""
101         if user_input.strip() == "/q":
102             raise AgentStop()
103
104         if not user_input.strip():
105             return ""
106
107         self.conversation.append({"role": "user", "content": user_input})
108
109         try:
110             thought = self.brain.think(self.conversation)
111             if thought.thinking:
112                 lines = thought.thinking.strip().split("\n")[:5]
113                 for i, line in enumerate(lines):
114                     prefix = "  💭 " if i == 0 else "     "
115                     print(f"\033[2m{prefix}{line}\033[0m")
116             text = thought.text or ""
117             self.conversation.append({"role": "assistant", "content": text})
118             return text
119         except Exception as e:
120             self.conversation.pop()  # Remove failed user message
121             return f"Error: {e}"
The Walkthrough:
- Lines 95-97: Accept a brain via dependency injection. Initialize an empty conversation list.
- Line 107: Append the user’s message to history before calling the brain.
- Lines 110-118: Call the brain, display up to five lines of thinking in dimmed text (
\033[2mis the ANSI escape code for dim,\033[0mresets it), extract the response, and append it to history. - Lines 119-121: If the API call fails, remove the user message we just added. This keeps the conversation in a valid state.
Pay attention to line 107: we add the user message before calling the brain. The brain needs to see the full conversation including the current message.
The Main Loop (Updated)
The main loop is now just a thin I/O wrapper:
126 def main():
127     brain = Claude()
128     agent = Agent(brain)
129     print("⚡ Nanocode v0.2 (Conversation Memory)")
130     print("Type '/q' to quit.\n")
131
132     while True:
133         try:
134             user_input = input("❯ ")
135             output = agent.handle_input(user_input)
136             if output:
137                 print(f"\n{output}\n")
138
139         except (AgentStop, KeyboardInterrupt):
140             print("\nExiting...")
141             break
142
143
144 if __name__ == "__main__":
145     main()
All the logic is in the Agent class. The loop just reads input, calls handle_input(), and prints the result. This separation makes the agent testable—we test Agent.handle_input() directly without needing to mock input() or print().
Verify the Tests Pass
Run the tests again:
1 pytest test_nanocode.py -v
1 test_nanocode.py::test_handle_input_returns_brain_response PASSED
2 test_nanocode.py::test_conversation_accumulates PASSED
3 test_nanocode.py::test_conversation_contains_correct_roles PASSED
4 test_nanocode.py::test_brain_receives_conversation PASSED
All green. The tests verify our implementation without making a single API call.
Test the Memory
Now test with the real brain:
1 python nanocode.py
Try this conversation:
 1 ❯ I am building a Python agent.
 2   💭 The user is telling me about their project. They want to build
 3      a Python agent. I should respond helpfully and ask what kind
 4      of agent they're building.
 5
 6 That sounds exciting! What kind of agent are you building?
 7
 8 ❯ What language am I using?
 9   💭 The user previously said they are building a Python agent.
10      The answer is Python.
11
12 You are using Python.
The conversation list is doing its job.
The Context Window Problem
You might be thinking: “Can I keep this running forever?”
No.
Every loop iteration, the messages list grows:
| Turn | Approximate Tokens |
|---|---|
| 1 | 50 |
| 10 | 5,000 |
| 100 | 50,000 |
Eventually, you hit the context limit: the desk space available for the current request and the output it generates. The capacity depends on the model. If the input alone exceeds Claude’s limit, the API returns 400 Bad Request. Generation can also reach the window boundary; newer Claude models then return stop_reason: "model_context_window_exceeded" rather than a 400.3
Our error handling on line 119 reports failed requests and removes the latest user message. A shorter next message may fit if the failed message caused the overflow. If the retained history alone is too long, every new request will still fail until we reduce that history.
For now, restarting the agent clears the history and gets you back on track. We’ll add proper context compaction—tracking token usage from the API response and automatically summarizing old messages before they overflow—when we build the feedback loop in Chapter 9. That’s where conversations actually blow up, and where the fix will earn its keep.
Wrapping Up
Claude remembers now—or rather, we’ve tricked it into thinking it does. The conversation list grows with every turn, and FakeBrain lets us test the whole thing without spending a cent.
Both patterns will carry through the rest of the book. Every brain we build (Claude, DeepSeek, Ollama) will implement the same think() interface, and FakeBrain will test them all.
One loose end: our code is hardwired to Anthropic’s API. If we want to add DeepSeek or a local model, we’d have to duplicate a lot of code.