第三章:无限循环
我们遇到了一个问题。
运行第二章的脚本两次。说“我的名字是爱丽丝。“Claude说你好。再次运行并询问“我的名字是什么?“Claude说“我不知道。”
这是因为大语言模型是无状态的。它们会完全失忆。每个请求对它们来说都像是第一次见面。
要构建一个智能体,我们需要通过创建人工记忆来解决这个问题。
记忆的假象
大语言模型中的“记忆“不是硬盘。它是一个日志文件。
当你与ChatGPT聊天时,它并不“记得“你5分钟前说过什么。在后台,代码会在每个新消息中将整个对话历史发送回模型。
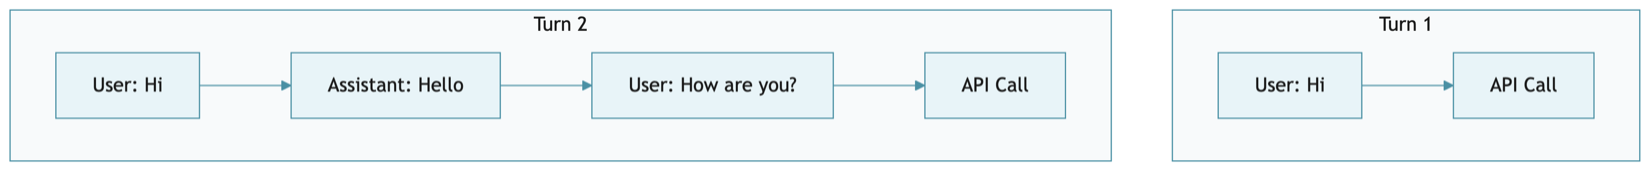
模型每次都会看到完整的对话记录。这就是诀窍所在。
我们将手动实现这个上下文循环。但首先,我们需要让我们的代码可测试。
测试问题
这是一个残酷的事实:你不能通过实际调用大语言模型来测试基于大语言模型的应用程序。
API调用速度慢(每次2-10秒),成本高(每次调用都需要真金白银),而且非确定性(每次可能得到不同的响应)。想象一下运行一个花费5美元且需要20分钟的测试套件。你永远不会去运行它。
解决方案是依赖注入。我们不在智能体内部硬编码API调用,而是传入一个“大脑“对象。在生产环境中,这个大脑就是Claude。在测试中,这个大脑是一个返回可预测响应的假对象。
在编写更多生产代码之前,我们将建立这个模式。
响应类型
在构建大脑之前,我们需要定义它返回什么。Claude的API会返回包含多个内容块的复杂JSON。我们需要简单的Python对象来处理这些数据。
上下文: Claude可以在单个响应中返回文本、工具调用,或两者都返回。我们需要数据类来表示这些可能性。
代码:
17 class ToolCall:
18     """A tool invocation request from the brain."""
19
20     def __init__(self, id, name, args):
21         self.id = id
22         self.name = name
23         self.args = args  # dict
ToolCall 表示大脑请求我们执行一个工具。id 是用于跟踪的唯一标识符(当我们向 Claude 报告结果时需要它)。name 是要运行的工具名称。args 是一个参数字典。
我们暂时不会使用 ToolCall——因为大脑还不能调用工具——但我们现在定义它是因为它是 Thought 响应类型的一部分。当我们添加工具后,Claude 想要读取文件或执行命令时就会返回这些内容。
26 class Thought:
27     """Standardized response from any Brain."""
28
29     def __init__(self, text=None, tool_calls=None):
30         self.text = text  # str or None
31         self.tool_calls = tool_calls or []  # list of ToolCall
Thought 是大脑思考后返回的结果。它可能包含文本、工具调用,或者两者都有,也可能两者都没有。这种抽象设计将使我们之后能够将 Claude 替换为 DeepSeek,而无需更改任何其他代码。
模拟大脑模式
现在我们可以构建一个用于测试的模拟大脑。
背景: 我们需要一个大脑模型,它能返回可预测的响应,追踪被调用的次数,并记录接收到的对话内容。
代码:
class FakeBrain:
    """Fake brain for testing - returns predictable responses."""

    def __init__(self, responses=None):
        self.responses = responses or [Thought(text="Fake response")]
        self.call_count = 0
        self.last_conversation = None

    def think(self, conversation):
        self.last_conversation = list(conversation)  # Store a copy
        if self.call_count < len(self.responses):
            response = self.responses[self.call_count]
            self.call_count += 1
            return response
        return Thought(text="No more responses")
这段代码应该放在 test_nanocode.py 中,而不是生产代码中。注意 FakeBrain 与我们真实的大脑具有相同的接口——一个接收对话并返回 Thought 的 think() 方法。
 |
附注: 这种模式——在测试中用可预测的伪对象替换真实依赖——被称为依赖注入。Martin Fowler 的文章“Mocks Aren’t Stubs“1解释了其中的变体(伪对象、存根、模拟对象、间谍对象)。对于 LLM 测试,通常只需要一个带有预设响应的简单伪对象就足够了。 |
定义成功标准
在编写生产代码之前,让我们先定义成功的标准。这些测试将指导我们的实现。
测试 1:大脑返回响应
1 def test_handle_input_returns_brain_response():
2     """Verify handle_input returns the brain's response text."""
3     brain = FakeBrain(responses=[Thought(text="Hello from brain!")])
4     agent = Agent(brain=brain)
5     result = agent.handle_input("hi")
6     assert result == "Hello from brain!"
注意我们将 brain=brain 传递给 Agent。这就是依赖注入的实际应用。
测试2:对话会累积
 1 def test_conversation_accumulates():
 2     """Verify conversation list grows with each interaction."""
 3     brain = FakeBrain(responses=[
 4         Thought(text="Response 1"),
 5         Thought(text="Response 2")
 6     ])
 7     agent = Agent(brain=brain)
 8
 9     agent.handle_input("First message")
10     assert len(agent.conversation) == 2  # user + assistant
11
12     agent.handle_input("Second message")
13     assert len(agent.conversation) == 4  # 2 users + 2 assistants
每次交互后,对话都应该同时包含用户消息和助手回复。
测试3:正确的消息结构
 1 def test_conversation_contains_correct_roles():
 2     """Verify conversation has correct role alternation."""
 3     brain = FakeBrain(responses=[Thought(text="AI response")])
 4     agent = Agent(brain=brain)
 5
 6     agent.handle_input("User message")
 7
 8     assert agent.conversation[0]["role"] == "user"
 9     assert agent.conversation[0]["content"] == "User message"
10     assert agent.conversation[1]["role"] == "assistant"
11     assert agent.conversation[1]["content"] == "AI response"
消息必须具有 Claude 期望的确切格式:{"role": "user", "content": "..."}。
测试 4:Brain 接收对话
 1 def test_brain_receives_conversation():
 2     """Verify brain.think is called with the conversation list."""
 3     brain = FakeBrain()
 4     agent = Agent(brain=brain)
 5
 6     agent.handle_input("Test message")
 7
 8     assert brain.last_conversation is not None
 9     assert len(brain.last_conversation) == 1
10     assert brain.last_conversation[0]["content"] == "Test message"
大脑必须接收完整的对话,而不仅仅是当前的消息。
现在运行这些测试——它们应该都会失败:
1 pytest test_nanocode.py -v
1 FAILED test_nanocode.py::test_handle_input_returns_brain_response
2 FAILED test_nanocode.py::test_conversation_accumulates
3 ...
好,现在让我们让它们通过测试。
Claude 类
现在到了核心部分。
**背景:**我们需要一个封装 Claude API 的类。它应该处理身份验证、发送对话历史,并将响应解析为一个 Thought。
代码:
36 class Claude:
37     """Claude API - the brain of our agent."""
38
39     def __init__(self):
40         self.api_key = os.getenv("ANTHROPIC_API_KEY")
41         if not self.api_key:
42             raise ValueError("ANTHROPIC_API_KEY not found in .env")
43         self.model = "claude-sonnet-4-6"
44         self.url = "https://api.anthropic.com/v1/messages"
45
46     def think(self, conversation):
47         headers = {
48             "x-api-key": self.api_key,
49             "anthropic-version": "2023-06-01",
50             "content-type": "application/json"
51         }
52         payload = {
53             "model": self.model,
54             "max_tokens": 4096,
55             "messages": conversation
56         }
57
58         print("(Claude is thinking...)")
59         response = requests.post(self.url, headers=headers, json=payload, timeout=120)
60         response.raise_for_status()
61         return self._parse_response(response.json()["content"])
详解:
- **第 39-41 行:**加载 API 密钥,如果密钥缺失则快速失败。
- **第 43-44 行:**存储配置。我们稍后会使配置模型变得可配置。
- 第 46 行:
think()方法是大脑的接口——与FakeBrain相同。 - **第 52-55 行:**负载包含
"messages": conversation——完整的历史记录,而不仅仅是当前消息。这就是上下文循环。 - **第 61 行:**将 Claude 的复杂响应格式解析为我们的简单
Thought。
现在是响应解析器:
63     def _parse_response(self, content):
64         """Convert Claude's response format to Thought."""
65         text_parts = []
66         tool_calls = []
67
68         for block in content:
69             if block["type"] == "text":
70                 text_parts.append(block["text"])
71             elif block["type"] == "tool_use":
72                 tool_calls.append(ToolCall(
73                     id=block["id"],
74                     name=block["name"],
75                     args=block["input"]
76                 ))
77
78         return Thought(
79             text="\n".join(text_parts) if text_parts else None,
80             tool_calls=tool_calls
81         )
Claude 的 API 会返回一个“内容块“列表。每个块都有一个 type —— 可能是 "text" 或 "tool_use"。我们将所有文本块收集到一个字符串中,并将 tool_use 块转换为 ToolCall 对象。
Agent 类(更新版)
现在我们更新第一章中的 Agent,使其能够接受大脑组件并维护对话历史。
代码:
 86 class Agent:
 87     """A coding agent with conversation memory."""
 88
 89     def __init__(self, brain):
 90         self.brain = brain
 91         self.conversation = []
 92
 93     def handle_input(self, user_input):
 94         """Handle user input. Returns output string, raises AgentStop to quit."""
 95         if user_input.strip() == "/q":
 96             raise AgentStop()
 97
 98         if not user_input.strip():
 99             return ""
100
101         self.conversation.append({"role": "user", "content": user_input})
102
103         try:
104             thought = self.brain.think(self.conversation)
105             text = thought.text or ""
106             self.conversation.append({"role": "assistant", "content": text})
107             return text
108         except Exception as e:
109             self.conversation.pop()  # Remove failed user message
110             return f"Error: {e}"
演练:
- **第 89-91 行:**通过依赖注入接收智能核心。初始化一个空的对话列表。
- **第 101 行:**在调用智能核心之前将用户消息添加到历史记录中。
- **第 103-107 行:**调用智能核心,提取文本,将响应添加到历史记录中。
- **第 108-110 行:**如果 API 调用失败,删除我们刚刚添加的用户消息。这样可以保持对话状态的有效性。
注意第 101 行:我们在调用智能核心之前添加用户消息。智能核心需要看到包含当前消息在内的完整对话。
主循环(已更新)
主循环现在只是一个简单的输入/输出包装器:
115 def main():
116     brain = Claude()
117     agent = Agent(brain)
118     print("⚡ Nanocode v0.2 (Conversation Memory)")
119     print("Type '/q' to quit.\n")
120
121     while True:
122         try:
123             user_input = input("❯ ")
124             output = agent.handle_input(user_input)
125             if output:
126                 print(f"\n{output}\n")
127
128         except (AgentStop, KeyboardInterrupt):
129             print("\nExiting...")
130             break
131
132
133 if __name__ == "__main__":
134     main()
所有的逻辑都在 Agent 类中。循环只是读取输入,调用 handle_input(),并打印结果。这种分离使得代理变得可测试——我们可以直接测试 Agent.handle_input(),而不需要模拟 input() 或 print()。
验证测试是否通过
再次运行测试:
1 pytest test_nanocode.py -v
1 test_nanocode.py::test_handle_input_returns_brain_response PASSED
2 test_nanocode.py::test_conversation_accumulates PASSED
3 test_nanocode.py::test_conversation_contains_correct_roles PASSED
4 test_nanocode.py::test_brain_receives_conversation PASSED
测试全部通过。这些测试验证了我们的实现,而没有发起一次 API 调用。
测试内存
现在用真实的大脑来测试:
1 python nanocode.py
来试试这段对话:
1 ❯ I am building a Python agent.
2 (Claude is thinking...)
3
4 That sounds exciting! Building a Python agent is a great project...
5
6 ❯ What language am I using?
7 (Claude is thinking...)
8
9 You are using Python.
对话列表正在发挥其作用。
上下文窗口问题
你可能在想:“我可以一直这样运行下去吗?”
不能。
每次循环迭代,messages列表都会增长:
| 轮次 | 大约令牌数 |
|---|---|
| 1 | 50 |
| 10 | 5,000 |
| 100 | 50,000 |
最终,你会达到上下文限制——Claude Sonnet是20万个令牌,DeepSeek是12.8万个,某些本地模型低至4千个。超过限制后,API会返回400 Bad Request。我们在第108行的错误处理会捕获这个错误并报告,这样代理就不会悄无声息地崩溃。但是对话实际上已经卡住了——由于历史记录仍然太长,之后的每条消息都会失败。
目前,重启代理可以清除历史记录并让你重新开始。在第9章构建反馈循环时,我们会添加适当的上下文压缩——从API响应中跟踪令牌使用情况,并在溢出之前自动总结旧消息。那时对话确实会膨胀,而且这个解决方案将发挥其价值。
总结
Claude现在能记住了——或者更确切地说,我们让它认为它记住了。对话列表在每一轮都会增长,而FakeBrain让我们可以在不花一分钱的情况下测试整个系统。
这两种模式将贯穿本书的其余部分。我们构建的每个大脑(Claude、DeepSeek、Ollama)都将实现相同的think()接口,而FakeBrain将测试它们所有。
还有一个遗留问题:我们的代码是硬编码到Anthropic的API的。如果我们想添加DeepSeek或本地模型,我们就必须复制大量代码。
https://martinfowler.com/articles/mocksArentStubs.html↩︎